Search the meaning,
not the filename.
Questions, examples, concepts and short explanations are indexed together—even when the wording is not exact.
71 published results for “Build SLM From Scratch”
Visual explanations 60
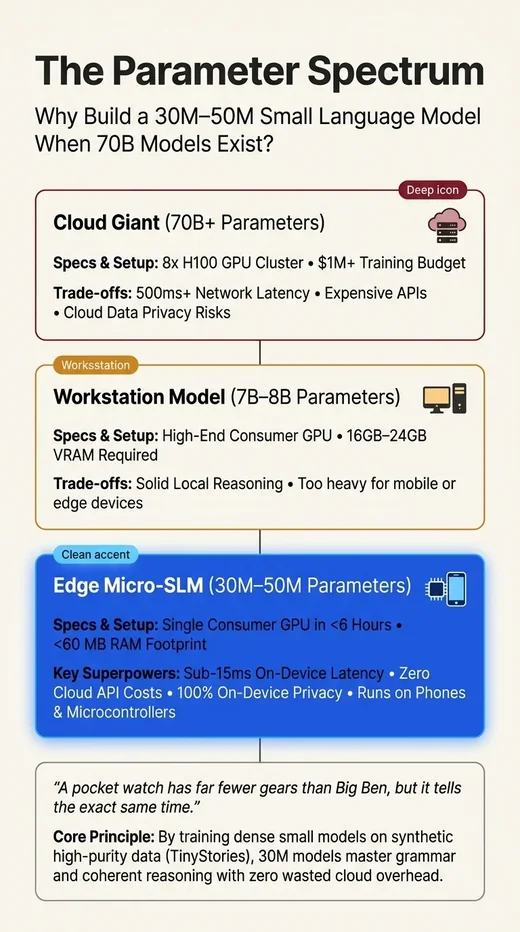 PICTURE 1 / 12What core mathematical principle governs the parameter spectrum cloud vs edge micro slm?Build SLM From Scratch · Slm Foundations
Classify language models across parameter scales based on hardware memory bandwidth, SRAM capacity, and KV-cache footprints.
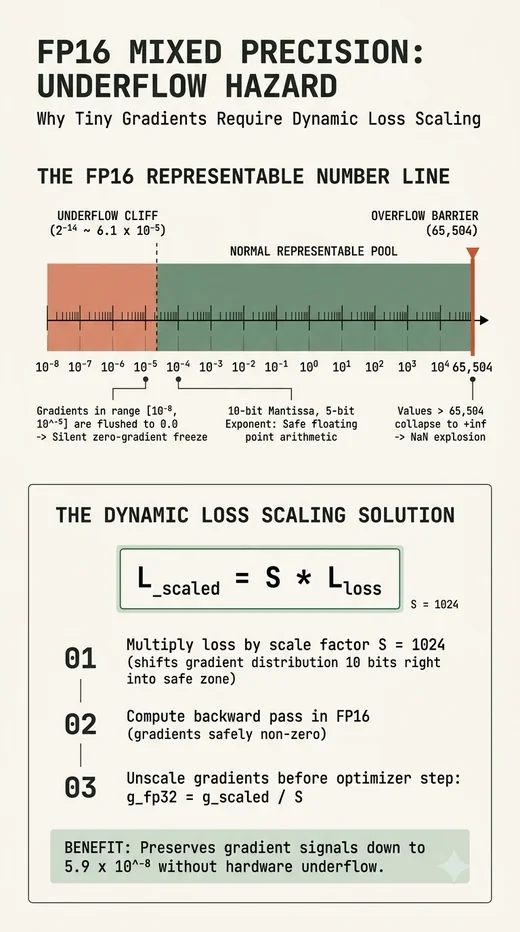 PICTURE 1 / 6How does mixed precision fp16 underflow hazard operate mathematically within the overall High-Performance SLM Training: FP16 Mixed Precision & Gradient Accumulation?Build SLM From Scratch · SLM High-Performance Training: Mixed Precision & Gradient Accumulation
Quantify and trace the mathematical mechanism of mixed precision fp16 underflow hazard across layer dimensions and operations.
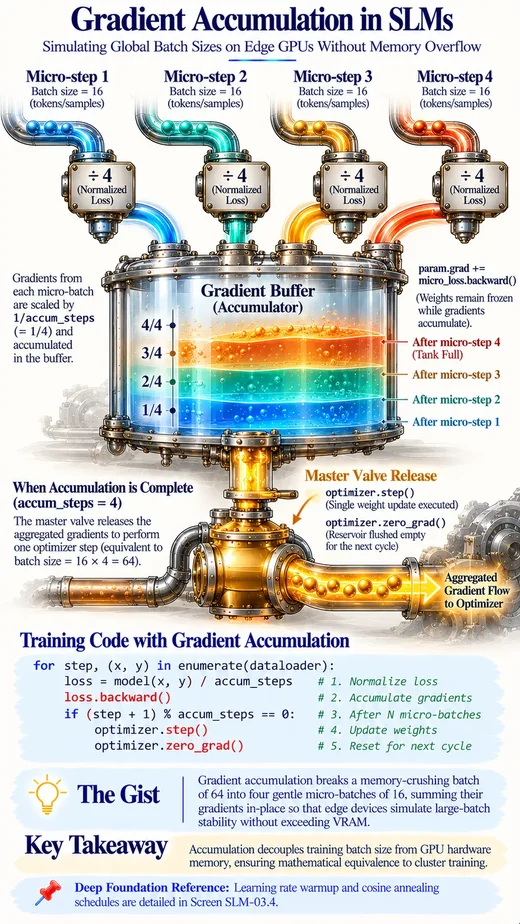 PICTURE 2 / 6How does gradient accumulation simulating large batches operate mathematically within the overall High-Performance SLM Training: FP16 Mixed Precision & Gradient Accumulation?Build SLM From Scratch · SLM High-Performance Training: Mixed Precision & Gradient Accumulation
Quantify and trace the mathematical mechanism of gradient accumulation simulating large batches across layer dimensions and operations.
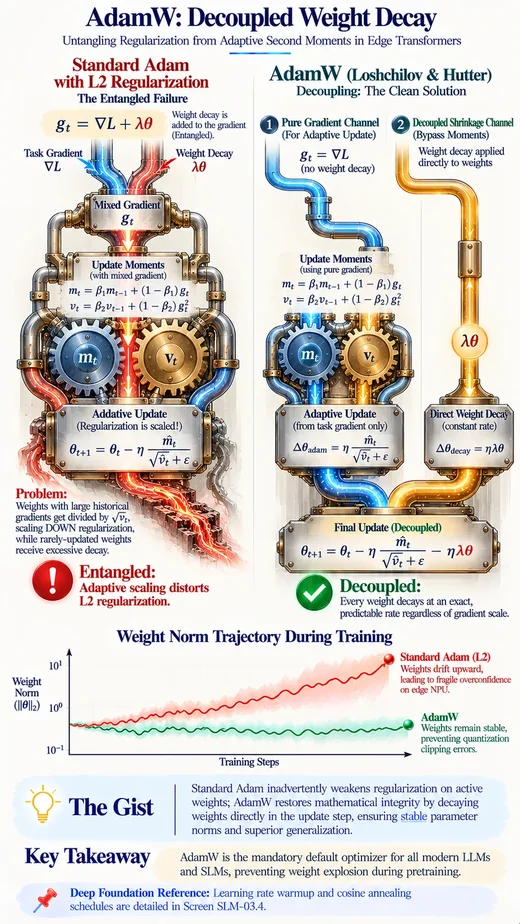 PICTURE 3 / 6How does adamw decoupled weight decay dynamics operate mathematically within the overall High-Performance SLM Training: FP16 Mixed Precision & Gradient Accumulation?Build SLM From Scratch · SLM High-Performance Training: Mixed Precision & Gradient Accumulation
Quantify and trace the mathematical mechanism of adamw decoupled weight decay dynamics across layer dimensions and operations.
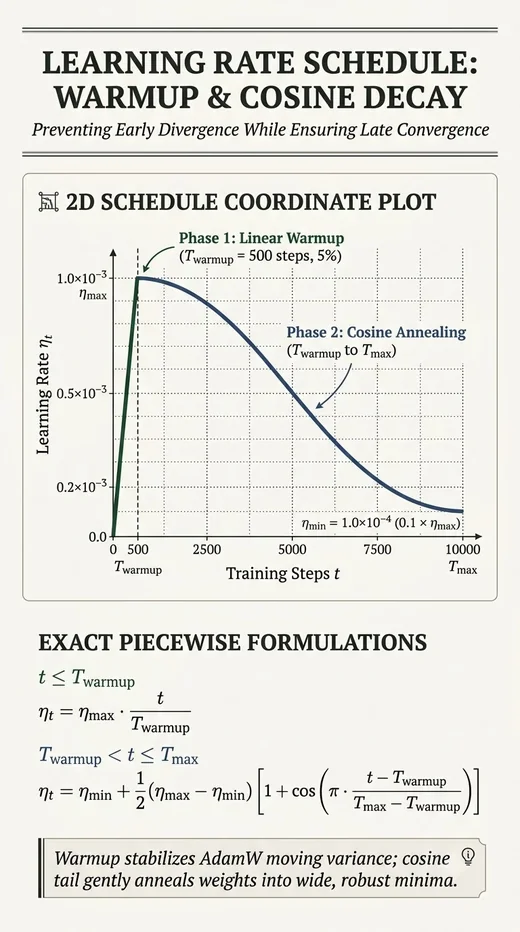 PICTURE 4 / 6How does learning rate warmup and cosine annealing operate mathematically within the overall High-Performance SLM Training: FP16 Mixed Precision & Gradient Accumulation?Build SLM From Scratch · SLM High-Performance Training: Mixed Precision & Gradient Accumulation
Quantify and trace the mathematical mechanism of learning rate warmup and cosine annealing across layer dimensions and operations.
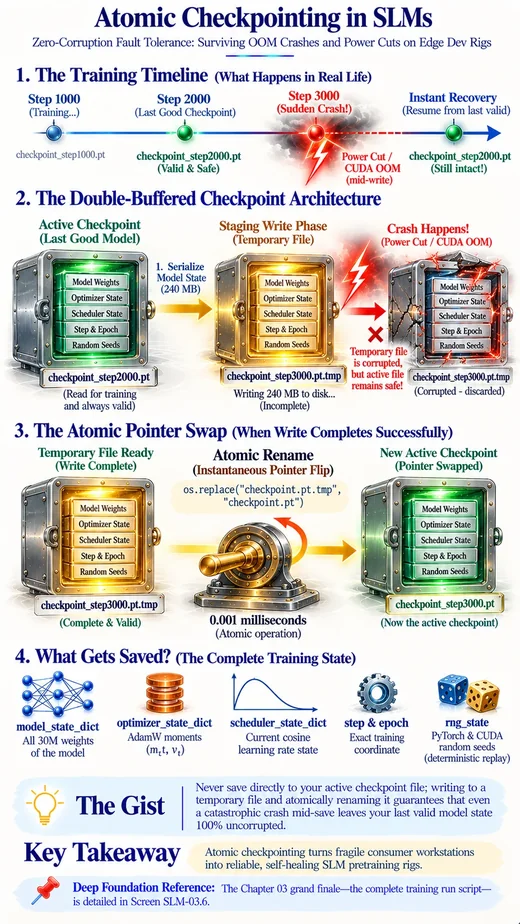 PICTURE 5 / 6How does atomic checkpointing and fault tolerance operate mathematically within the overall High-Performance SLM Training: FP16 Mixed Precision & Gradient Accumulation?Build SLM From Scratch · SLM High-Performance Training: Mixed Precision & Gradient Accumulation
Quantify and trace the mathematical mechanism of atomic checkpointing and fault tolerance across layer dimensions and operations.
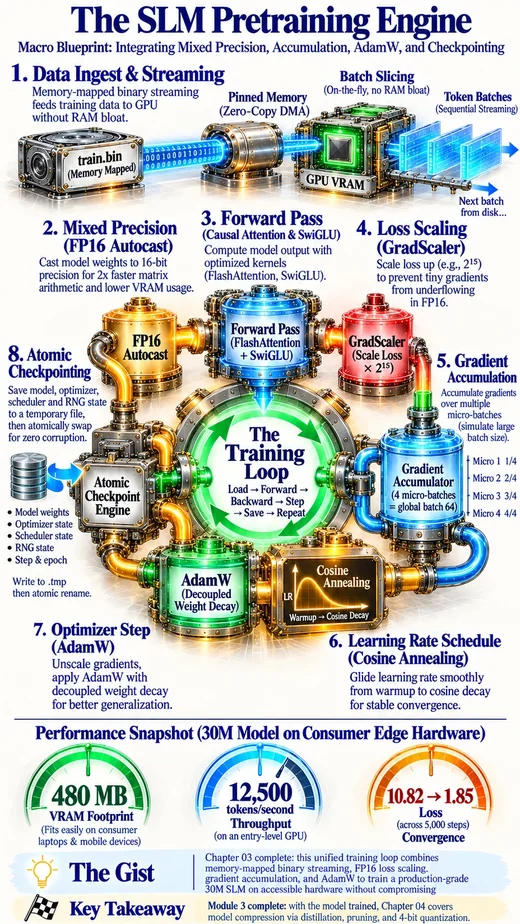 PICTURE 6 / 6How does complete slm training loop macro blueprint operate mathematically within the overall High-Performance SLM Training: FP16 Mixed Precision & Gradient Accumulation?Build SLM From Scratch · SLM High-Performance Training: Mixed Precision & Gradient Accumulation
Quantify and trace the mathematical mechanism of complete slm training loop macro blueprint across layer dimensions and operations.
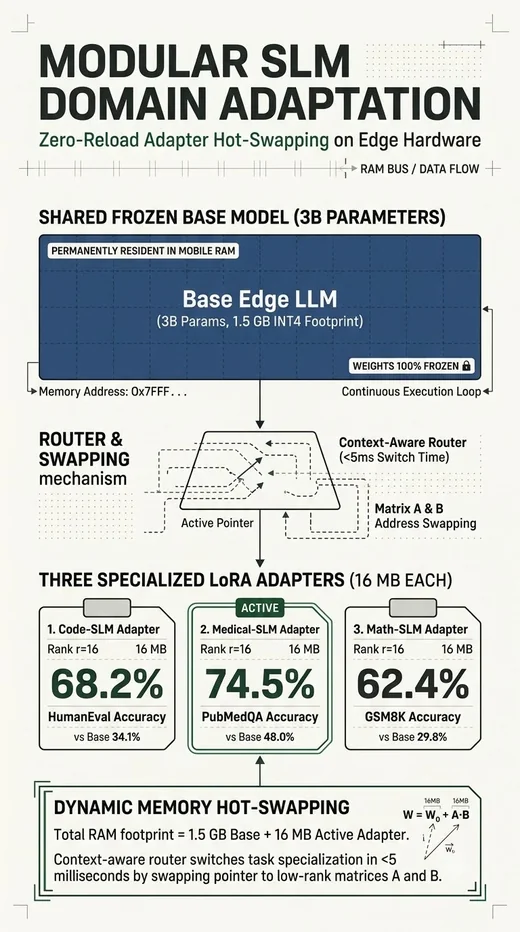 PICTURE 3 / 6How does domain adaptation specialized slm roles operate mathematically within the overall LoRA & QLoRA: Low-Rank Adapter Fine-Tuning on Edge Hardware?Build SLM From Scratch · Parameter-Efficient Tuning: LoRA, QLoRA & Mobile KV Cache
Quantify and trace the mathematical mechanism of domain adaptation specialized slm roles across layer dimensions and operations.
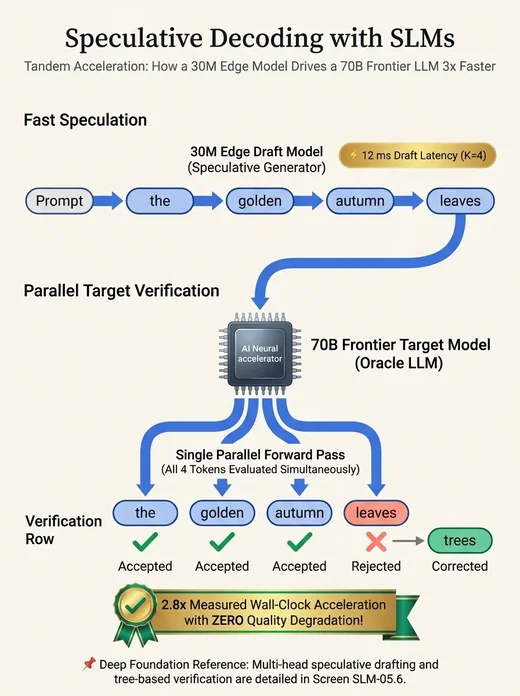 PICTURE 5 / 6How does speculative decoding slm draft acceleration operate mathematically within the overall LoRA & QLoRA: Low-Rank Adapter Fine-Tuning on Edge Hardware?Build SLM From Scratch · Parameter-Efficient Tuning: LoRA, QLoRA & Mobile KV Cache
Quantify and trace the mathematical mechanism of speculative decoding slm draft acceleration across layer dimensions and operations.
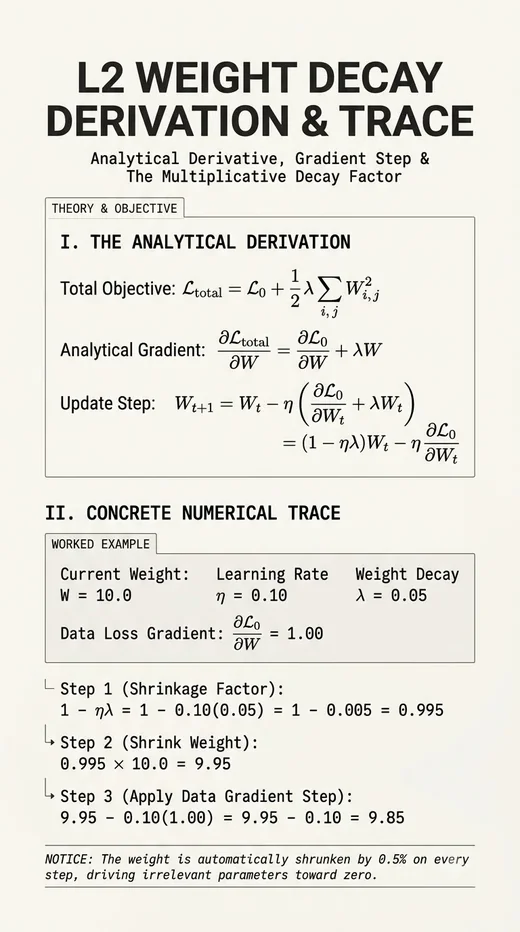 PICTURE 3 / 6How does the analytical gradient of the L2 penalty translate into a multiplicative weight decay factor during gradient descent updates?Build Neural Network From Scratch · Weight Regularization: L1 Sparsity, L2 Ridge & Weight Decay Calculus
Differentiating the L2 penalty $\frac{\lambda}{2} \|W\|_2^2$ produces $\lambda W$, which transforms standard gradient descent into a two-step update that contracts weights by $(1 - \eta \lambda)$ before subtracting data gradients.
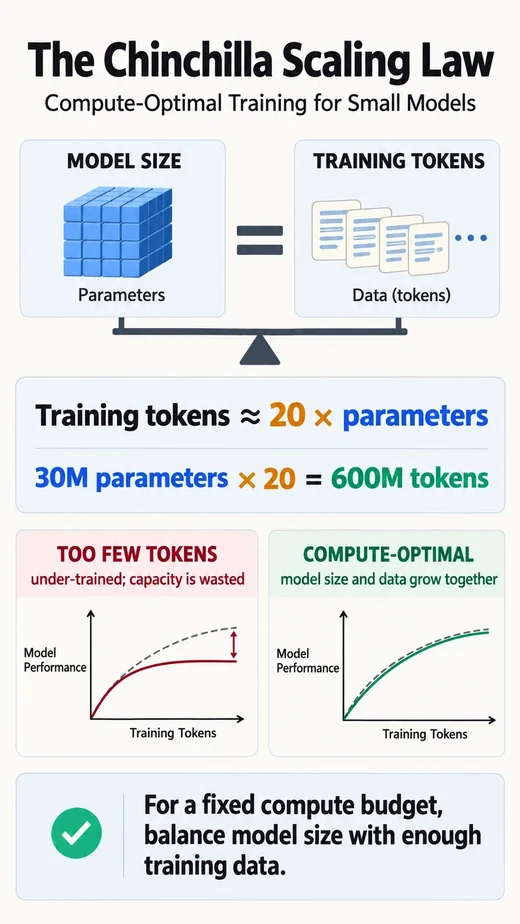 PICTURE 2 / 12What core mathematical principle governs the chinchilla law data saturation in slms?Build SLM From Scratch · Slm Foundations
Balance parameters and tokens according to Hoffmann et al. scaling laws, and exploit deliberate overtraining for inference efficiency.
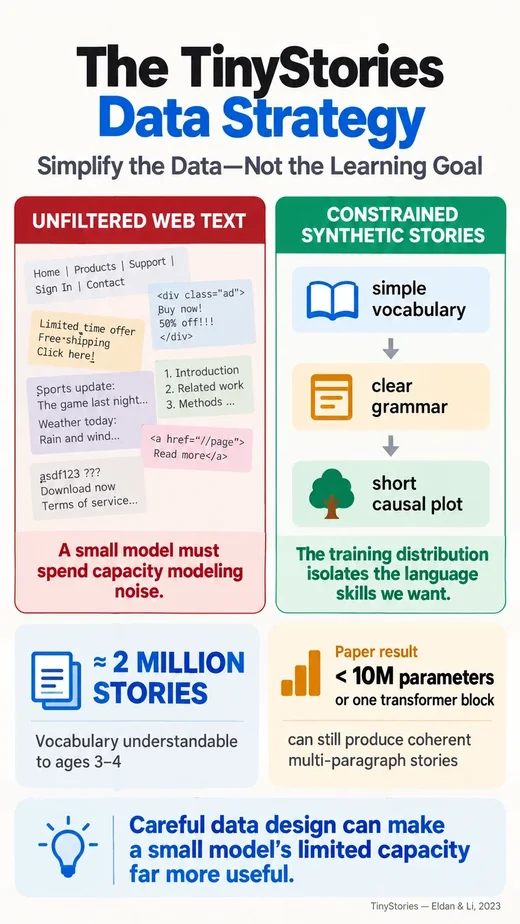 PICTURE 3 / 12What core mathematical principle governs the tinystories data strategy?Build SLM From Scratch · Slm Foundations
Synthesize high-density, low-noise training distributions to teach complex reasoning to micro-models with minimal parameters.
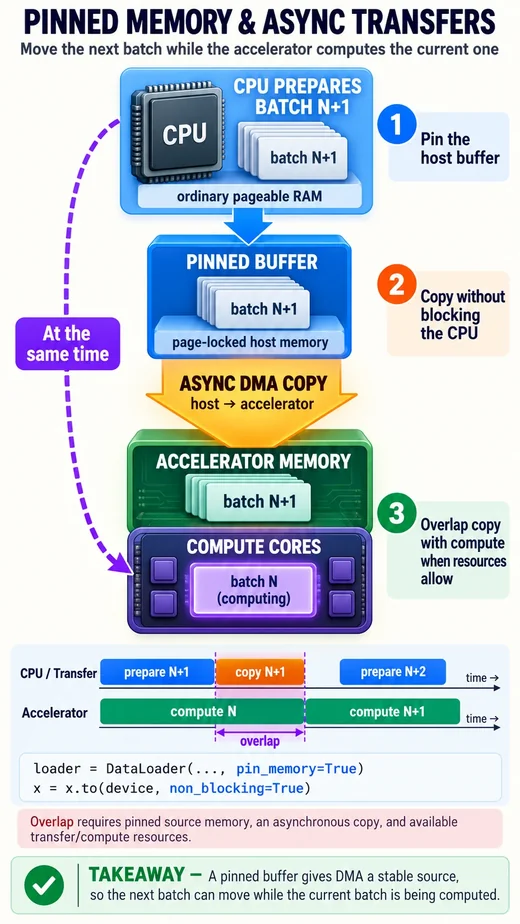 PICTURE 6 / 12How does page-locked host memory allow Direct Memory Access (DMA) controllers to stream token batches across PCIe without CPU intervention?Build SLM From Scratch · Slm Foundations
Pinned memory locks RAM buffers so GPUs can pull batches directly across the PCIe bus while Tensor Cores simultaneously compute the previous batch.
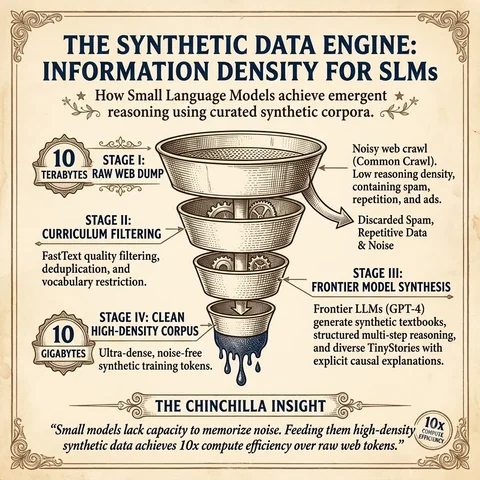 PICTURE 8 / 12How does Synthetic Data Curation: The TinyStories Information Density Funnel operate mathematically at scale?Build SLM From Scratch · Slm Foundations
Title in navy serif: "The Synthetic Data Engine: Information Density for SLMs". Subtitle: "How Small Language Models achieve emergent reasoning using curated synthetic corpora."
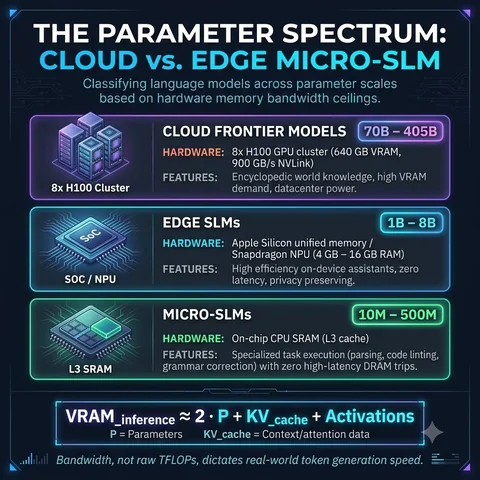 PICTURE 9 / 12How does The Parameter Spectrum: Cloud Frontiers to Edge Micro-SLMs operate mathematically at scale?Build SLM From Scratch · Slm Foundations
Title in white sans-serif: "The Parameter Spectrum: Cloud vs. Edge Micro-SLM". Subtitle in muted cyan: "Classifying language models across parameter scales based on hardware memory bandwidth ceilings."
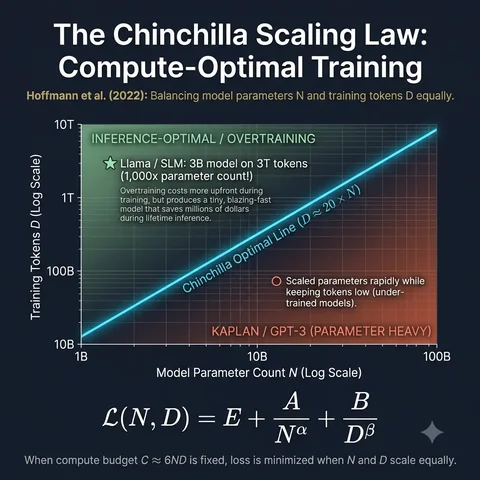 PICTURE 10 / 12How does The Chinchilla Scaling Law: Data Saturation in SLMs operate mathematically at scale?Build SLM From Scratch · Slm Foundations
Title in white sans-serif: "The Chinchilla Scaling Law: Compute-Optimal Training". Subtitle in muted gold: "Hoffmann et al. (2022): Balancing model parameters N and training tokens D equally."
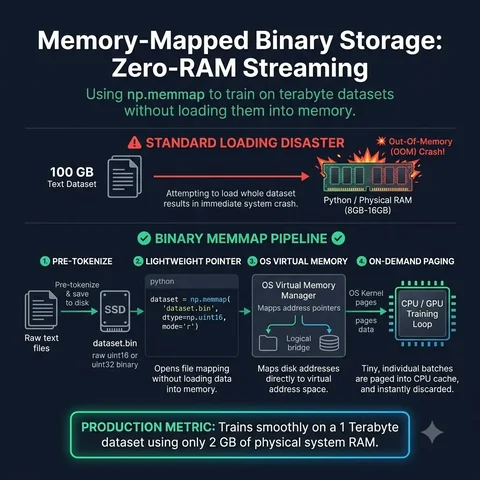 PICTURE 11 / 12How does Memory-Mapped Binary Disk Storage: Zero-RAM Dataset Streaming operate mathematically at scale?Build SLM From Scratch · Slm Foundations
Title in white sans-serif: "Memory-Mapped Binary Storage: Zero-RAM Streaming". Subtitle in muted emerald: "Using np.memmap to train on terabyte datasets without loading them into memory."
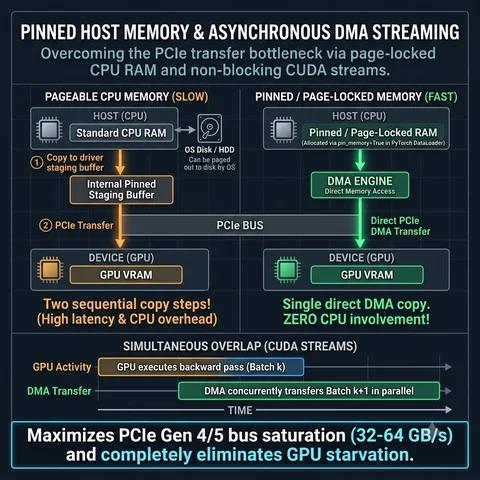 PICTURE 12 / 12How does Pinned Host Memory & Asynchronous DMA GPU Streaming operate mathematically at scale?Build SLM From Scratch · Slm Foundations
Title in white sans-serif: "Pinned Host Memory & Asynchronous DMA Streaming". Subtitle in muted cyan: "Overcoming the PCIe transfer bottleneck via page-locked CPU RAM and non-blocking CUDA streams."
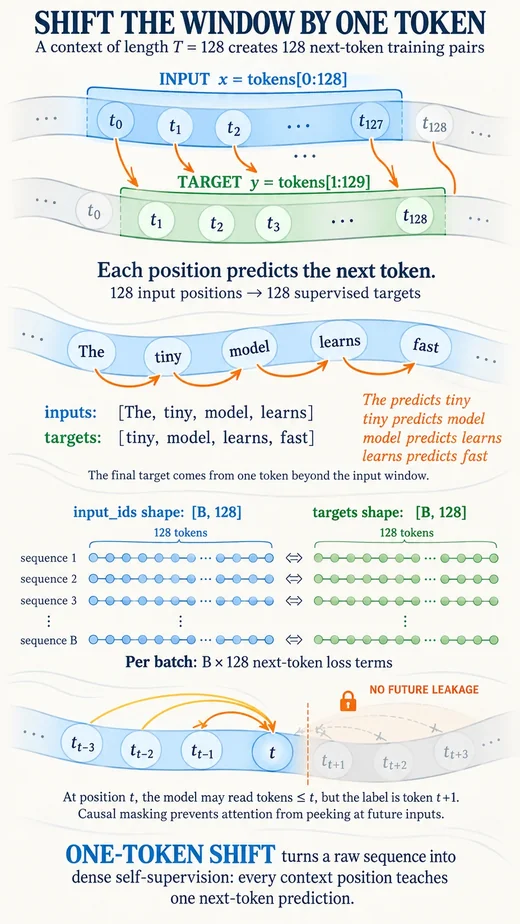 PICTURE 1 / 18How does shifted context window next token pairs operate mathematically within the overall Edge-Optimized Transformer: Grouped Query Attention & FlashAttention?Build SLM From Scratch · Edge Transformer Architecture: RMSNorm, SwiGLU & GQA
Quantify and trace the mathematical mechanism of shifted context window next token pairs across layer dimensions and operations.
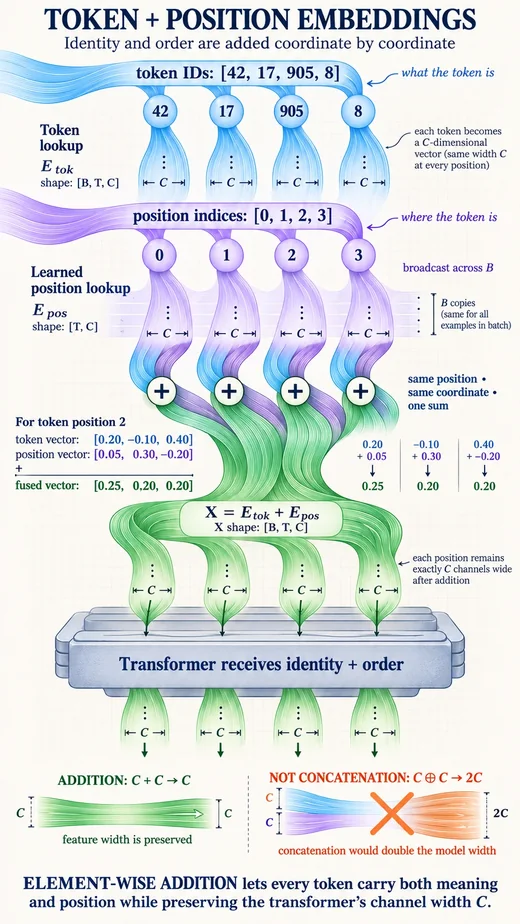 PICTURE 4 / 18How does token and position embedding fusion operate mathematically within the overall Edge-Optimized Transformer: Grouped Query Attention & FlashAttention?Build SLM From Scratch · Edge Transformer Architecture: RMSNorm, SwiGLU & GQA
Quantify and trace the mathematical mechanism of token and position embedding fusion across layer dimensions and operations.
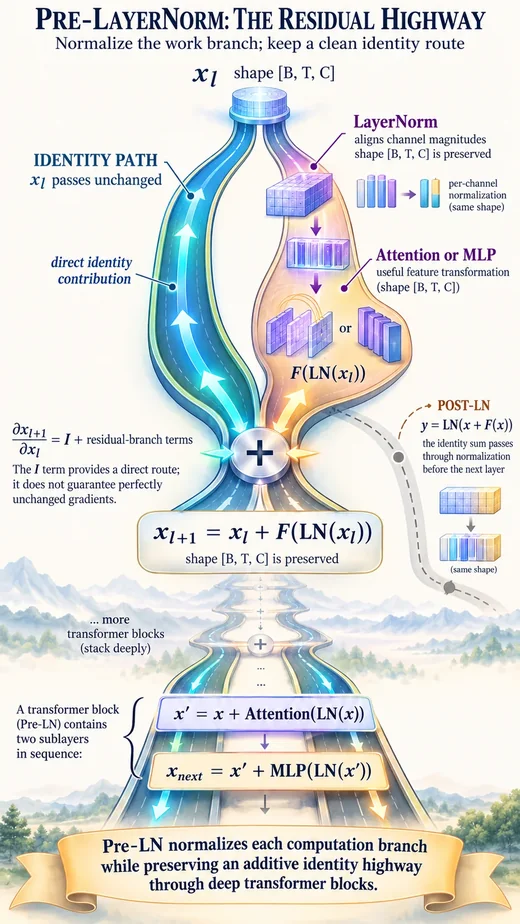 PICTURE 5 / 18How does pre layernorm residual highway operate mathematically within the overall Edge-Optimized Transformer: Grouped Query Attention & FlashAttention?Build SLM From Scratch · Edge Transformer Architecture: RMSNorm, SwiGLU & GQA
Quantify and trace the mathematical mechanism of pre layernorm residual highway across layer dimensions and operations.
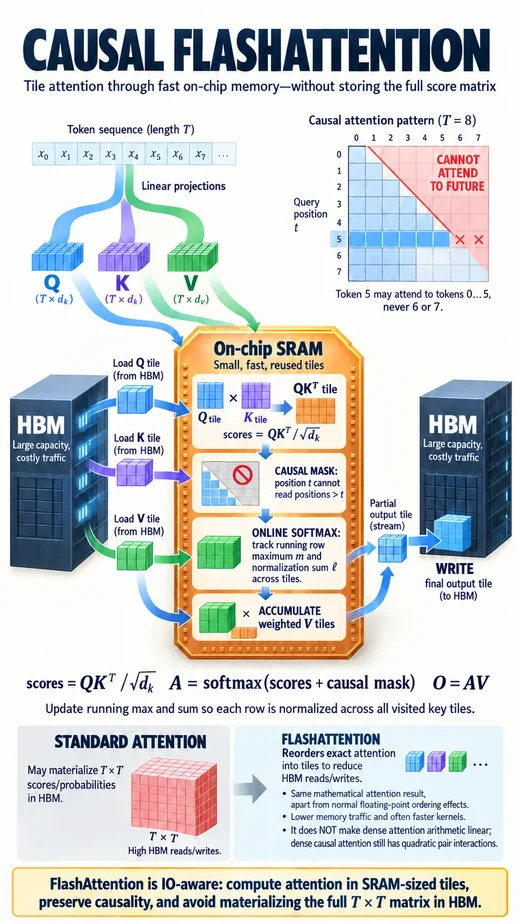 PICTURE 6 / 18How does causal flashattention memory tiling operate mathematically within the overall Edge-Optimized Transformer: Grouped Query Attention & FlashAttention?Build SLM From Scratch · Edge Transformer Architecture: RMSNorm, SwiGLU & GQA
Quantify and trace the mathematical mechanism of causal flashattention memory tiling across layer dimensions and operations.
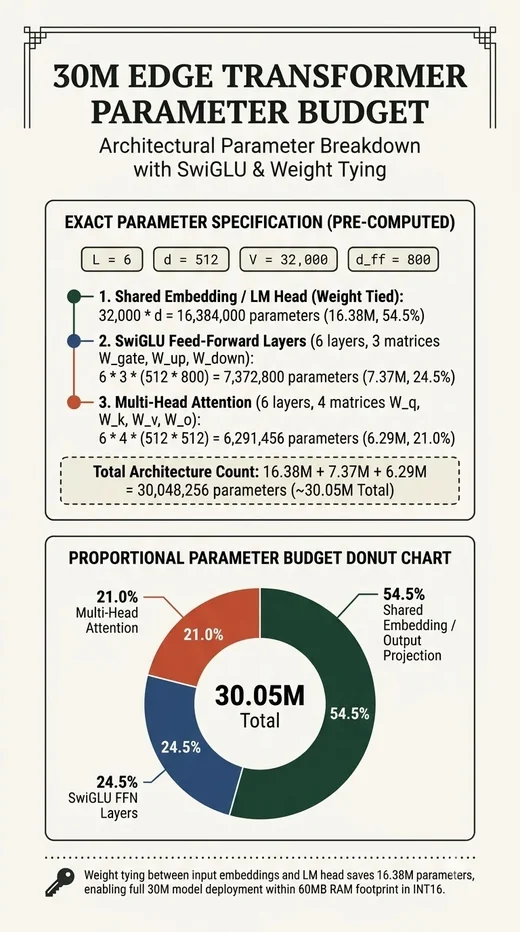 PICTURE 7 / 18How does mlp expansion and weight tying budget operate mathematically within the overall Edge-Optimized Transformer: Grouped Query Attention & FlashAttention?Build SLM From Scratch · Edge Transformer Architecture: RMSNorm, SwiGLU & GQA
Quantify and trace the mathematical mechanism of mlp expansion and weight tying budget across layer dimensions and operations.
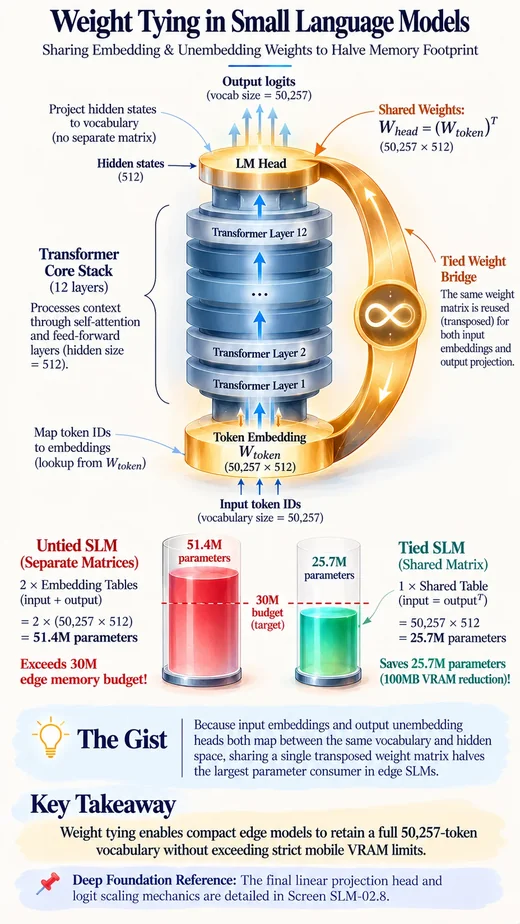 PICTURE 8 / 18How does weight tying tied embeddings edge operate mathematically within the overall Edge-Optimized Transformer: Grouped Query Attention & FlashAttention?Build SLM From Scratch · Edge Transformer Architecture: RMSNorm, SwiGLU & GQA
Quantify and trace the mathematical mechanism of weight tying tied embeddings edge across layer dimensions and operations.
Lessons 9
LESSONSlm FoundationsBuild SLM From ScratchWhat core mathematical principle governs the parameter spectrum cloud vs edge micro slm?
LESSONSLM High-Performance Training: Mixed Precision & Gradient AccumulationBuild SLM From ScratchHow do we train Small Language Models on modest GPU hardware using mixed-precision FP16/BF16 and gradient accumulation without numerical underflow or throughput bottlenecks?
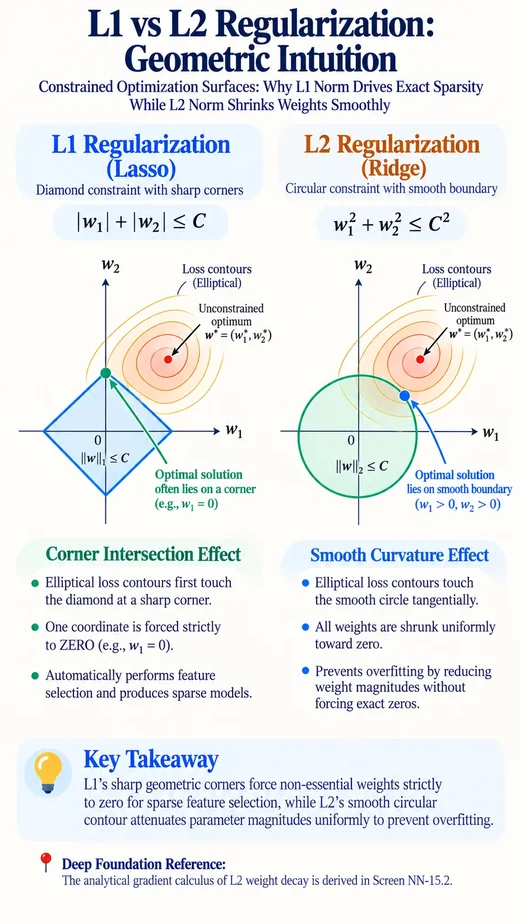 LESSONWeight Regularization: L1 Sparsity, L2 Ridge & Weight Decay CalculusBuild Neural Network From Scratch
How do mathematical penalties on weight magnitudes prevent overfitting, and why does L1 create exact zeros while L2 shrinks weights smoothly?
LESSONEdge Transformer Architecture: RMSNorm, SwiGLU & GQABuild SLM From ScratchHow do modern Small Language Models redesign self-attention and normalization to fit high-throughput reasoning onto battery-constrained mobile and edge NPUs?
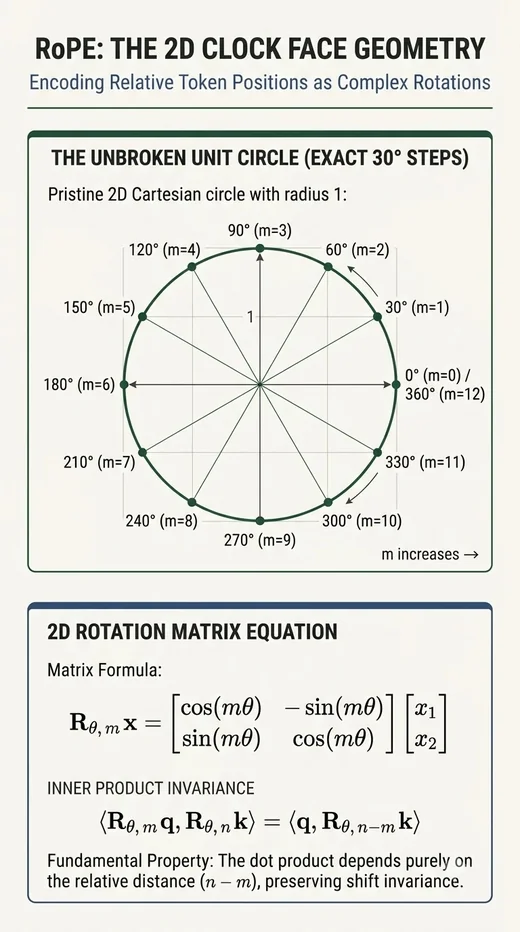 LESSONRotary Position Embedding (RoPE) ArchitectureBuild SLM From Scratch
How do 2D clock-face rotations encode relative token positions directly into complex attention inner products?
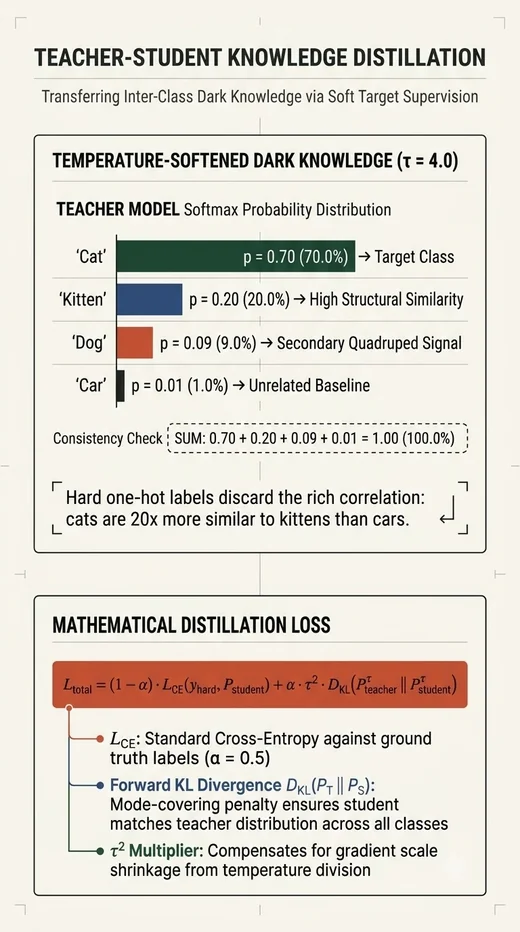 LESSONModel Compression: Knowledge Distillation, Pruning & 4-Bit QuantizationBuild SLM From Scratch
How do we compress a multi-billion parameter model into a compact footprint that runs smoothly on a phone NPU using knowledge distillation, pruning, and 4-bit quantization?
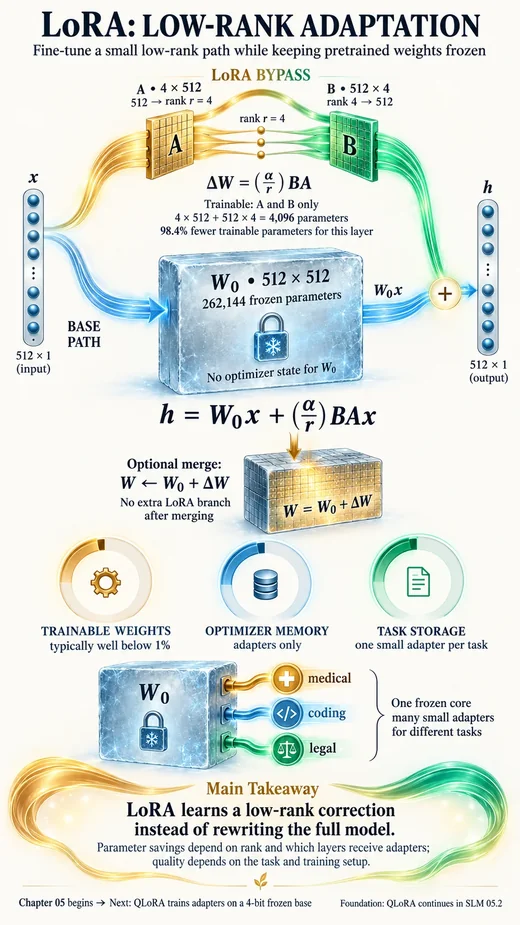 LESSONParameter-Efficient Tuning: LoRA, QLoRA & Mobile KV CacheBuild SLM From Scratch
How do low-rank matrix decomposition (LoRA) and 4-bit NormalFloat quantization (QLoRA) enable fine-tuning on consumer hardware, and how is the KV cache optimized on mobile devices?
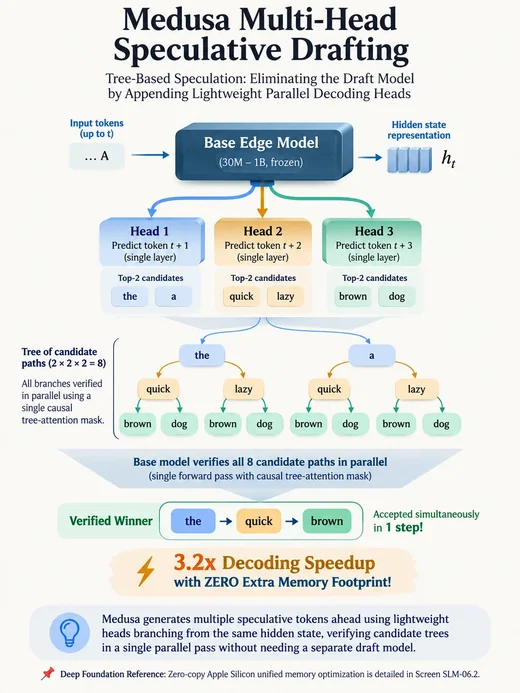 LESSONOn-Device Capstone: Speculative Heads, Unified Memory & Edge RAGBuild SLM From Scratch
How do multiple speculative decoding heads (Medusa), Apple Silicon unified zero-copy memory, on-device voice streaming, and private local RAG unite into a complete edge AI application?
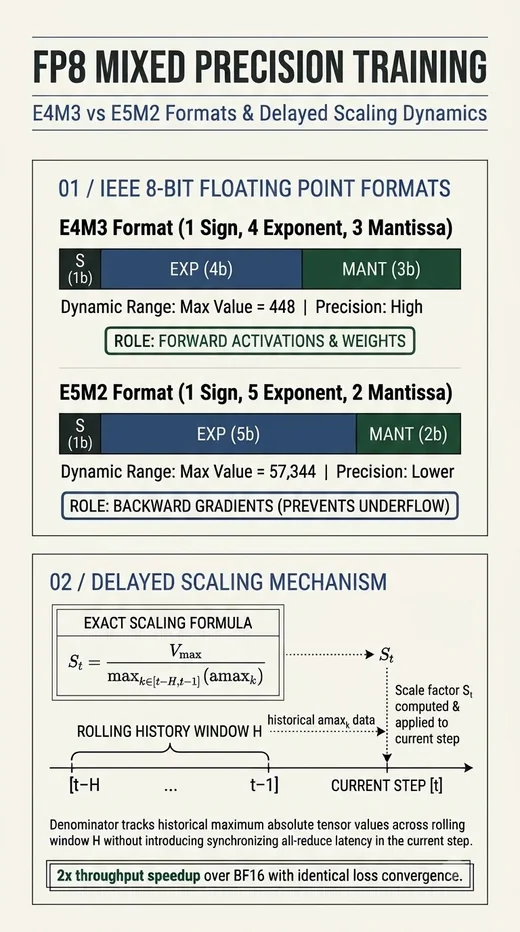 LESSONFrontier Scaling and Capstone: FP8 Precision, Mixture of Depths, NIAH, and Unified LLM ArchitectureBuild LLM From Scratch
How does 8-bit floating point training double GPU GEMM throughput while preventing gradient underflow via delayed scaling?