Search the meaning,
not the filename.
Questions, examples, concepts and short explanations are indexed together—even when the wording is not exact.
80 published results for “Build LLM From Scratch”
Visual explanations 69
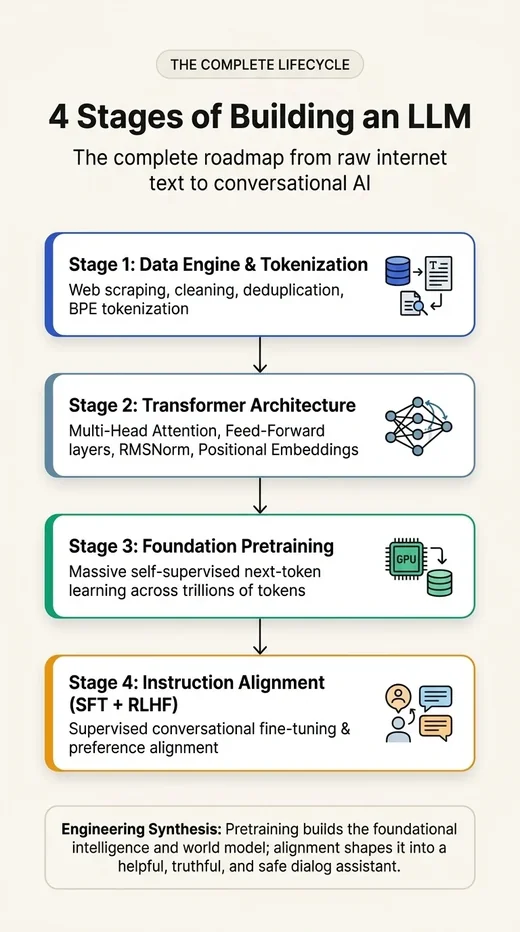 PICTURE 1 / 3What are the four architectural and computational phases required to build a conversational LLM from scratch?Build LLM From Scratch · Four Stages Of Building LLM
Synthesize the four pillars of LLM construction: Data Engineering, Base Pretraining, Supervised Fine-Tuning, and Preference Alignment.
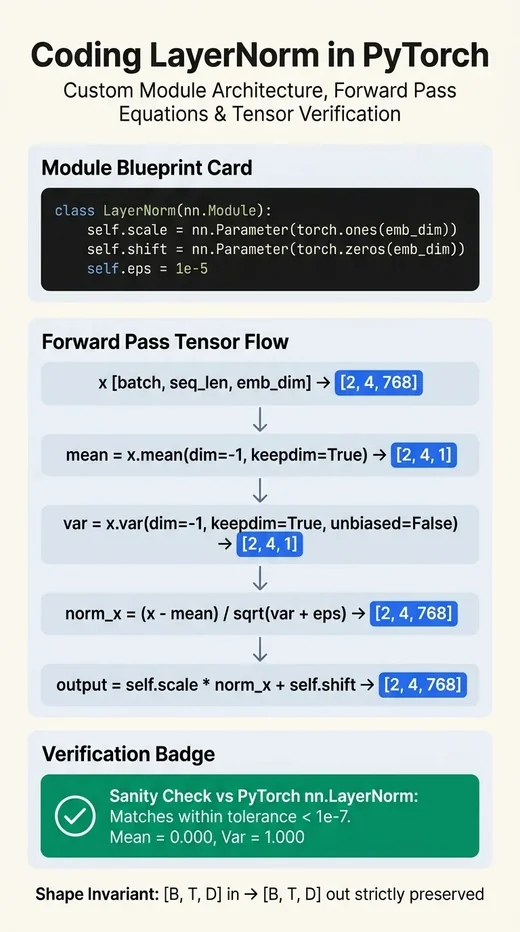 PICTURE 6 / 11How do you implement LayerNorm from scratch in PyTorch matching nn.LayerNorm behavior?Build LLM From Scratch · Layer Normalization
Write a custom PyTorch module with learnable gamma and beta parameters, computing mean and variance across dim=-1 with keepdim=True.
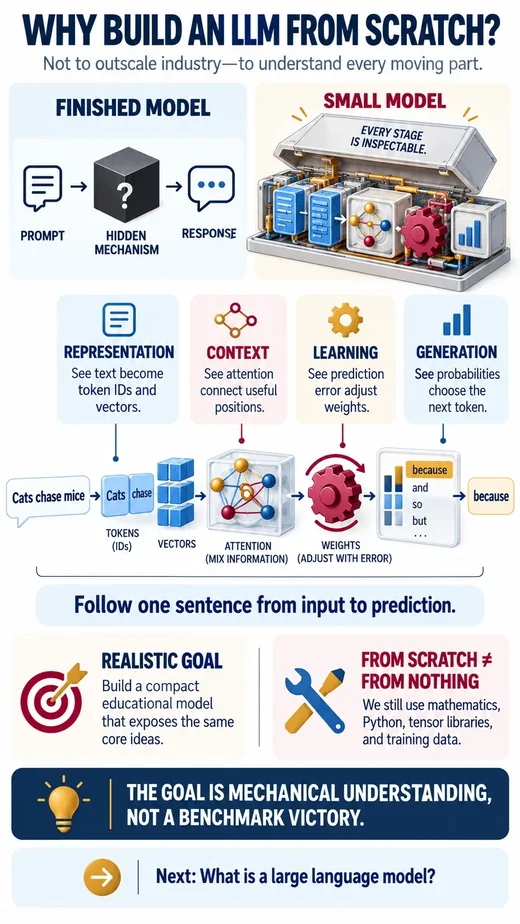 PICTURE 5 / 12Why is implementing an LLM line-by-line in pure PyTorch essential for deep engineering competence?Build LLM From Scratch · Preface
Demystify high-level framework abstractions by implementing tensor operations, attention heads, and backprop directly.
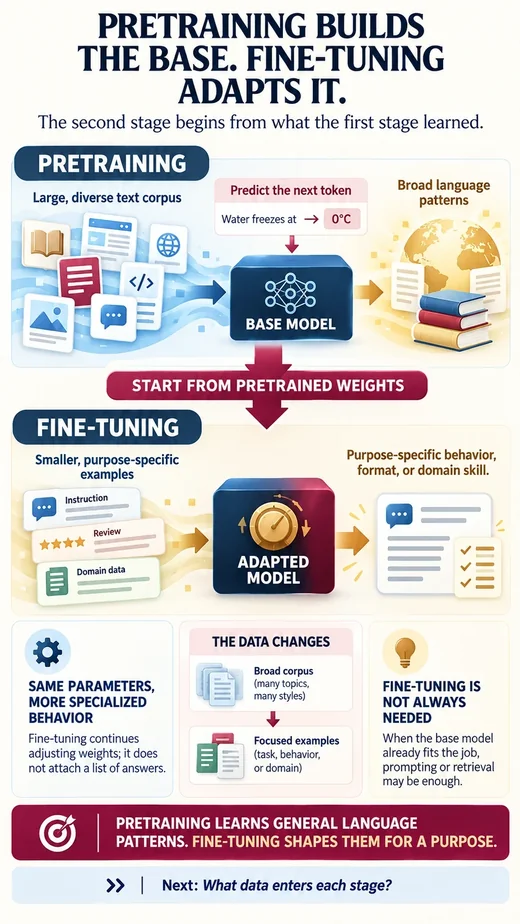 PICTURE 10 / 12Why is training an LLM divided into pretraining on raw corpora followed by fine-tuning on targeted instructions?Build LLM From Scratch · Preface
Analyze the functional division of labor between self-supervised foundation pretraining and supervised post-training adaptation.
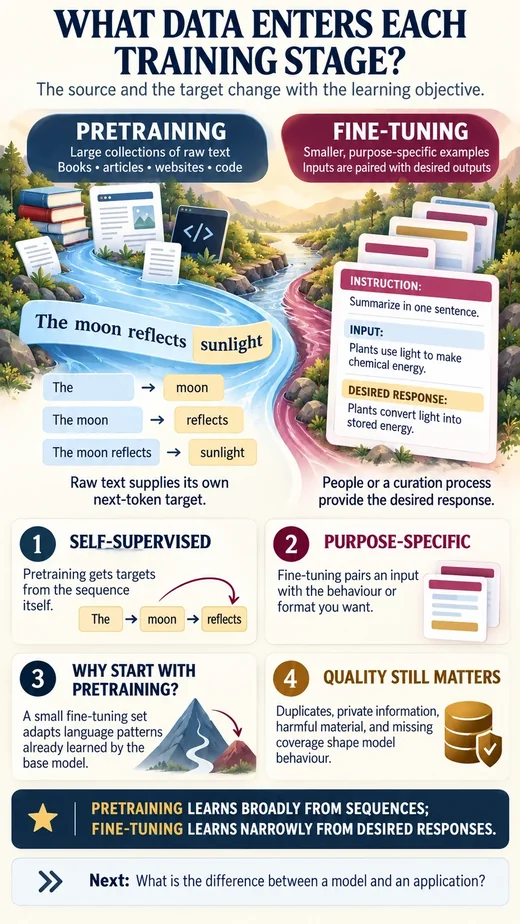 PICTURE 11 / 12How do the volume, curation standards, and formatting of training data differ across the LLM development lifecycle?Build LLM From Scratch · Preface
Examine the composition, filtering pipelines, and dataset structures used in pretraining versus post-training.
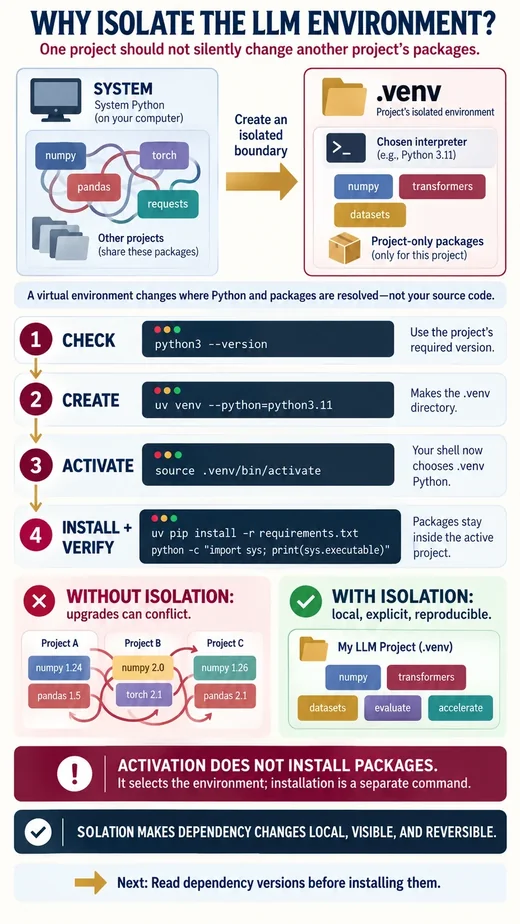 PICTURE 7 / 12Why do LLM development projects require strict environment isolation compared to standard software development?Build LLM From Scratch · Setting Python Environment
Analyze the architectural risks of system Python contamination and evaluate how isolated environments prevent dependency drift and ABI incompatibilities.
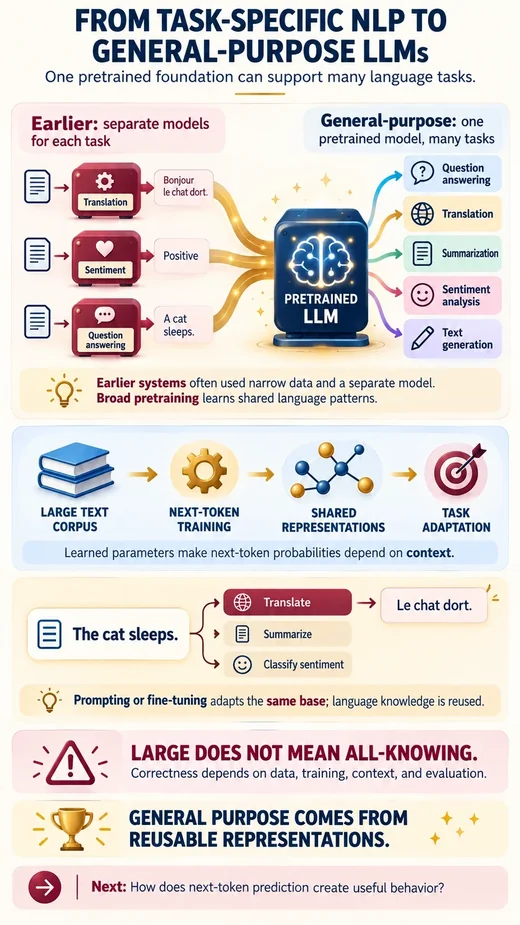 PICTURE 1 / 16How did natural language processing transition from isolated, task-specific pipelines to unified general-purpose foundation models?Build LLM From Scratch · Intro to LLM
Examine the paradigm shift from handcrafted per-task architectures to a single autoregressive transformer trained on web-scale data.
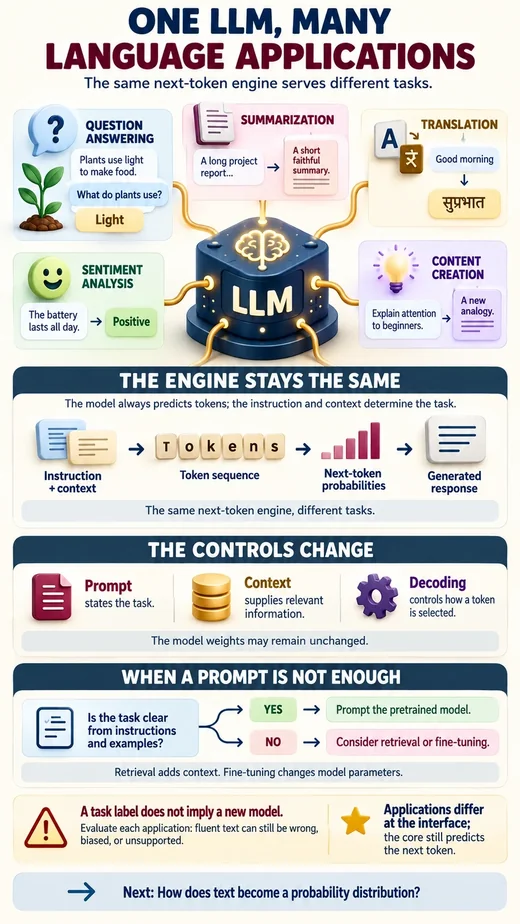 PICTURE 6 / 16How does the single generative engine of an LLM power diverse commercial applications across industries?Build LLM From Scratch · Intro to LLM
Map the application spectrum of LLMs from code generation and legal reasoning to synthetic data generation and agentic tool use.
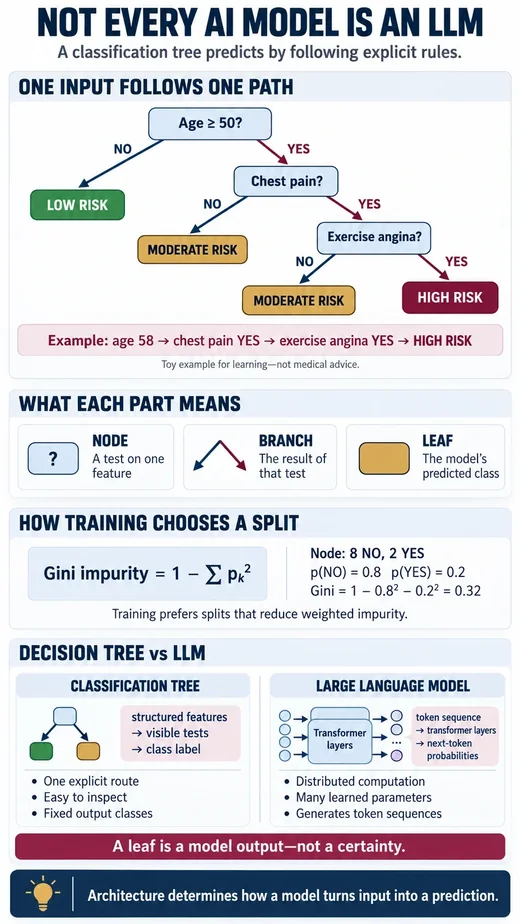 PICTURE 13 / 16How do Large Language Models differ algorithmically and structurally from other foundational AI architectures like CNNs, GNNs, and Diffusion models?Build LLM From Scratch · Intro to LLM
Distinguish autoregressive LLMs from vision classifiers, graph neural networks, and continuous diffusion systems.
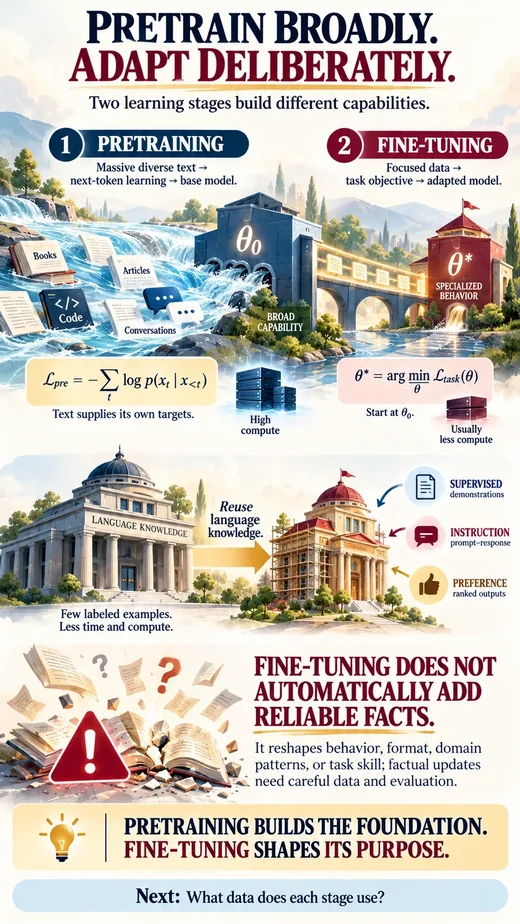 PICTURE 1 / 7Why is the lifecycle of an LLM fundamentally separated into self-supervised pretraining and supervised fine-tuning?Build LLM From Scratch · Pretraining vs Finetuning
Contrast the computational, data, and optimization profiles of pretraining foundational representations versus fine-tuning task behaviors.
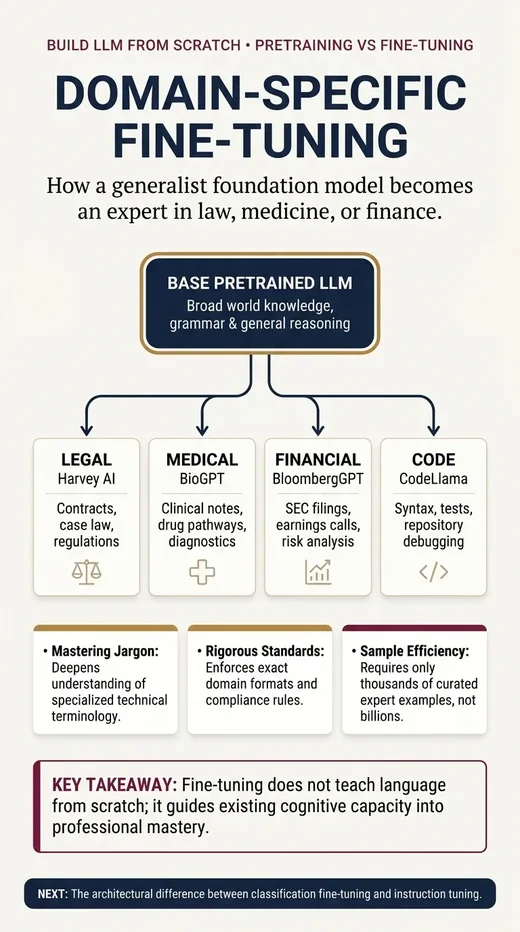 PICTURE 4 / 7How does domain-adaptive continued pretraining and fine-tuning specialize a base LLM for law, medicine, or finance?Build LLM From Scratch · Pretraining vs Finetuning
Examine domain adaptation techniques, continued pretraining on specialized corpora, and preventing catastrophic forgetting.
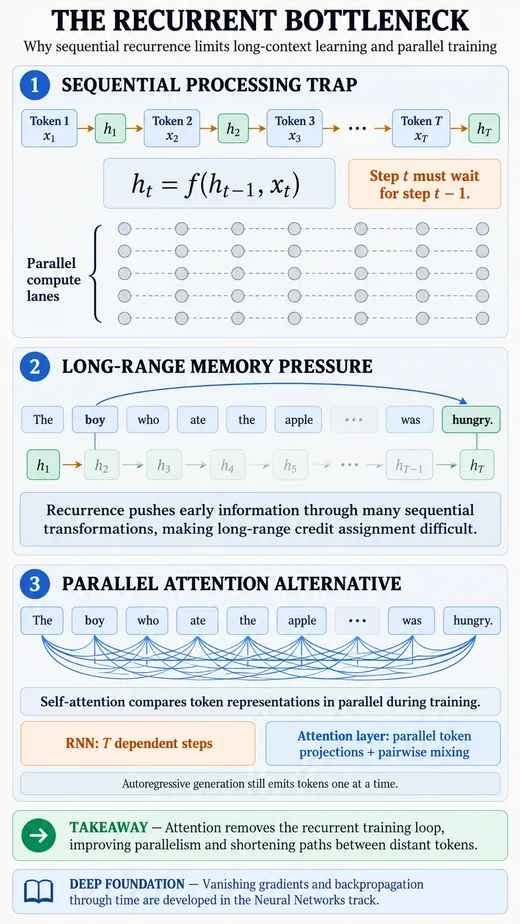 PICTURE 7 / 7Why do recurrent neural networks suffer from an information and gradient bottleneck over long sequences, and how did this failure necessitate the transformer?Build LLM From Scratch · Pretraining vs Finetuning
Recurrent networks serialize computation through a single fixed-size hidden state h_t, causing early context to be overwritten and gradients prod(W_hh) to exponentially vanish or explode.
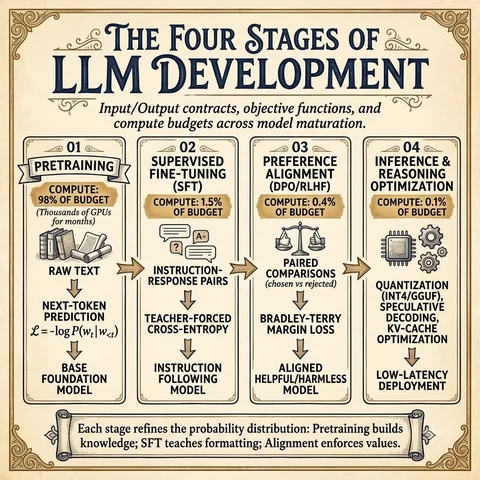 PICTURE 3 / 3How does The Four Stages of LLM Development: Contracts and Compute operate mathematically at scale?Build LLM From Scratch · Four Stages Of Building LLM
Title in navy serif: "The Four Stages of LLM Development". Subtitle: "Input/Output contracts, objective functions, and compute budgets across model maturation."
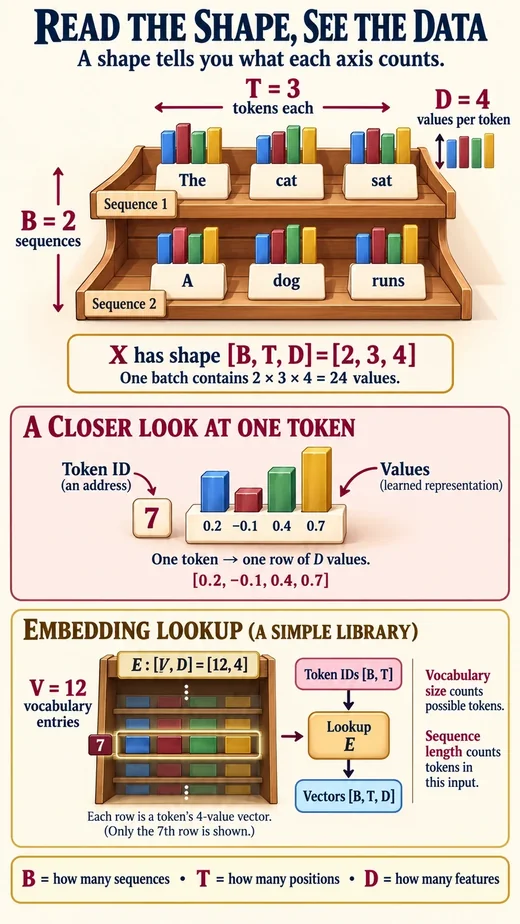 PICTURE 2 / 4How do multidimensional tensor shapes encode batch size, sequence length, and embedding dimensions across the LLM pipeline?Build LLM From Scratch · Input Output Pairs
Deconstruct the geometric meaning of rank-2, rank-3, and rank-4 tensors in PyTorch (`(B, T)`, `(B, T, d)`, `(B, h, T, d_k)`).
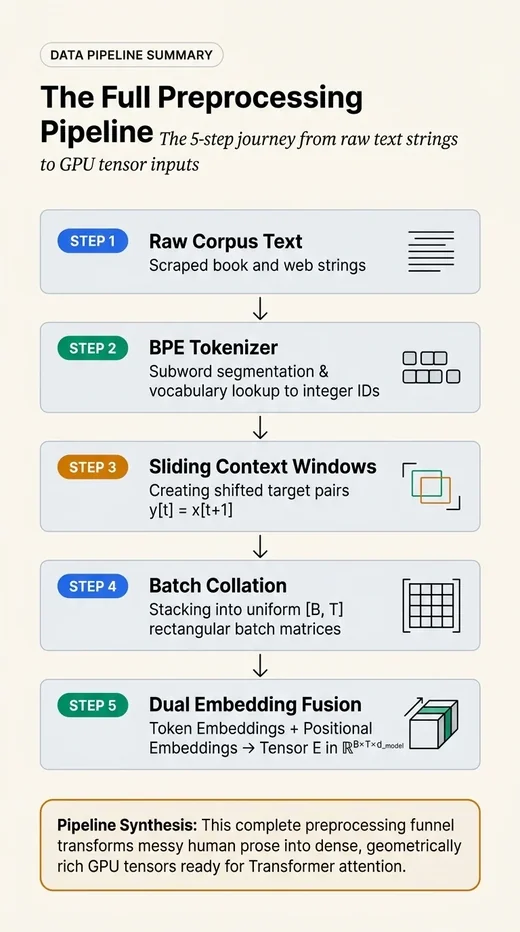 PICTURE 1 / 3What is the complete end-to-end data processing journey from raw text strings to GPU tensor inputs ready for Layer 1?Build LLM From Scratch · Preprocessing Summary
Synthesize the entire data preprocessing pipeline: Unicode text -> BPE tokenization -> integer IDs -> sliding window Dataset -> DataLoader batching -> token and positional embedding addition.
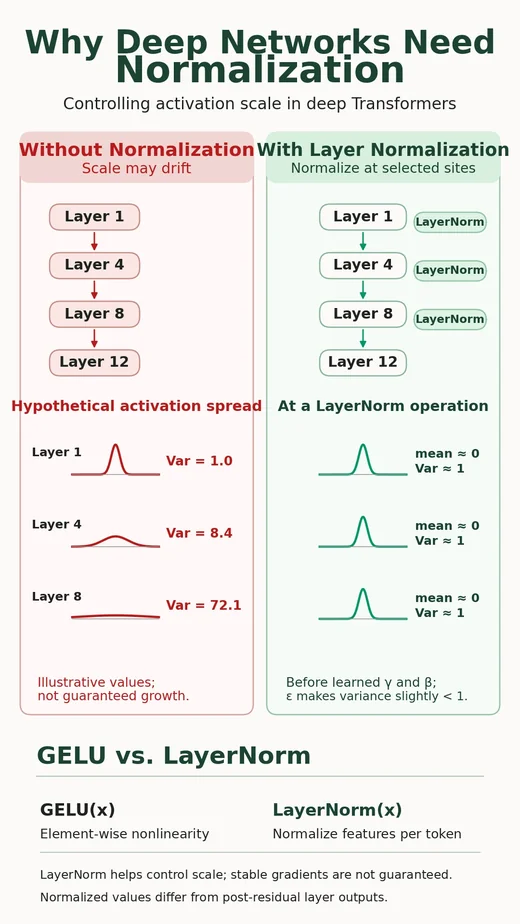 PICTURE 1 / 11Why do deep transformer networks suffer from internal covariate shift and exploding/vanishing gradients without normalization?Build LLM From Scratch · Layer Normalization
Stacked linear and non-linear layers cause activation scales to drift and compound exponentially, destabilizing backpropagation gradients.
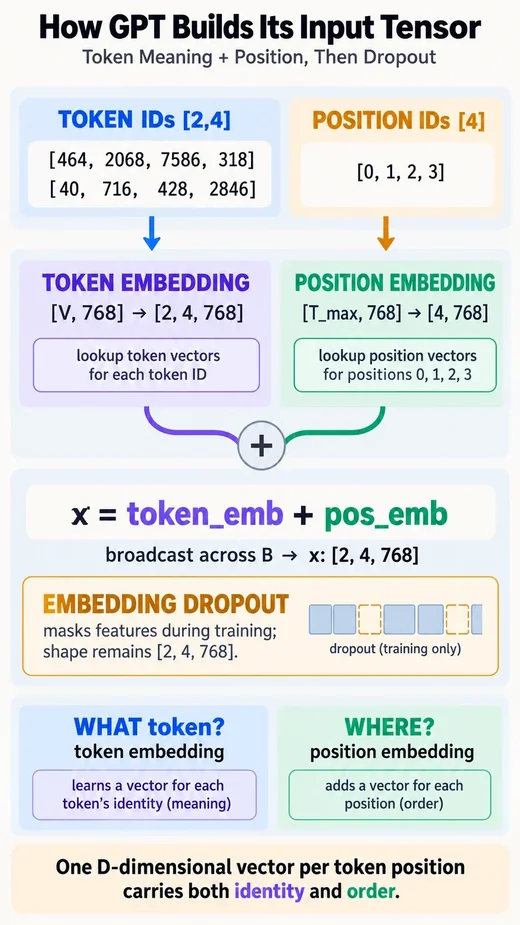 PICTURE 1 / 8How does GPT-2 (124M) construct its unified input tensor from discrete token IDs and positional embeddings?Build LLM From Scratch · GPT-2 (124M)
GPT-2 sums discrete token embeddings from matrix W_E with learned positional embeddings from matrix W_P to produce an input tensor of shape (B, T, 768).
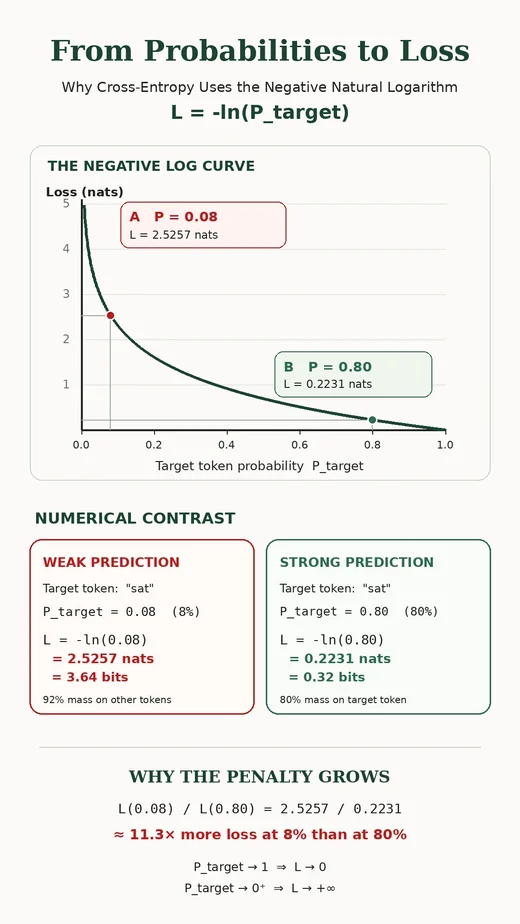 PICTURE 1 / 20How does the need for a loss function in llms operate mathematically within the overall LLM Loss Engine: Cross-Entropy & Perplexity?Build LLM From Scratch · LLM Loss Engine: Target Shifting, Cross-Entropy & Perplexity
Quantify and trace the mathematical mechanism of the need for a loss function in llms across layer dimensions and operations.
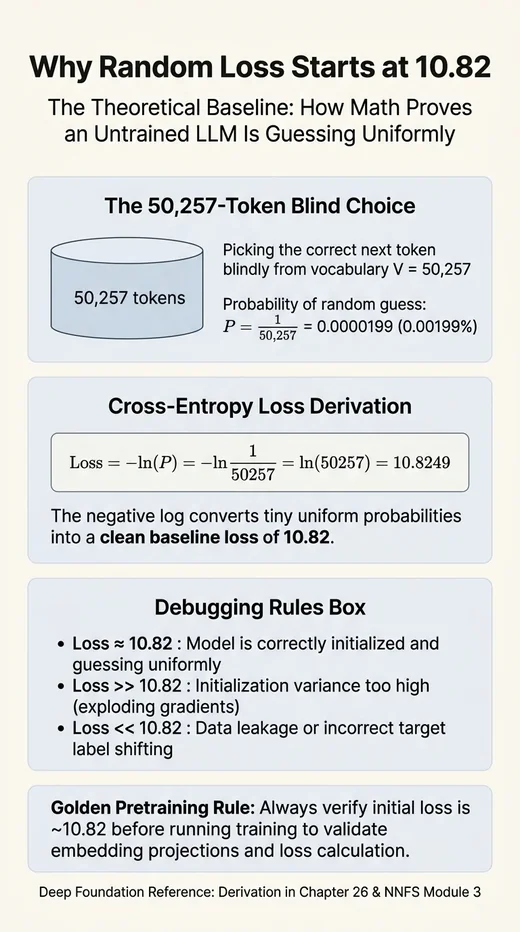 PICTURE 2 / 20How does bridge why random loss starts at 10 82 operate mathematically within the overall LLM Loss Engine: Cross-Entropy & Perplexity?Build LLM From Scratch · LLM Loss Engine: Target Shifting, Cross-Entropy & Perplexity
Quantify and trace the mathematical mechanism of bridge why random loss starts at 10 82 across layer dimensions and operations.
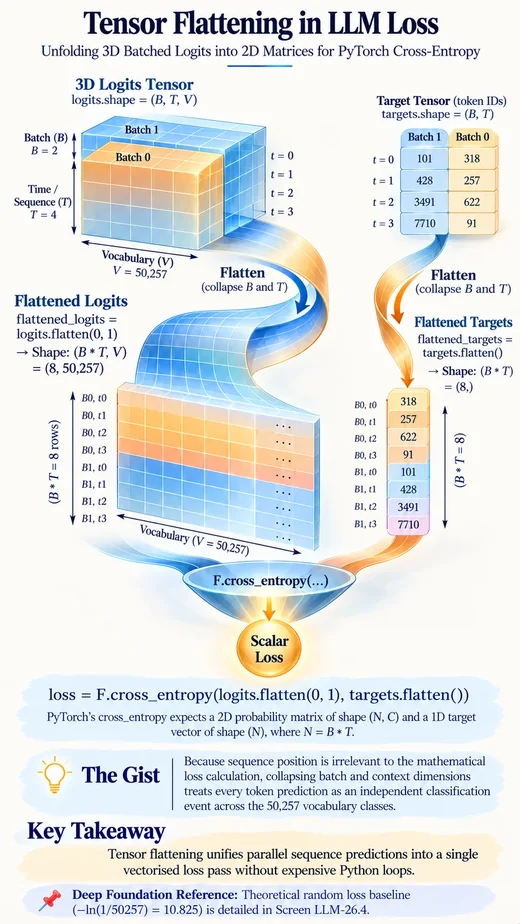 PICTURE 5 / 20How does flattening 3d logits for cross entropy operate mathematically within the overall LLM Loss Engine: Cross-Entropy & Perplexity?Build LLM From Scratch · LLM Loss Engine: Target Shifting, Cross-Entropy & Perplexity
Quantify and trace the mathematical mechanism of flattening 3d logits for cross entropy across layer dimensions and operations.
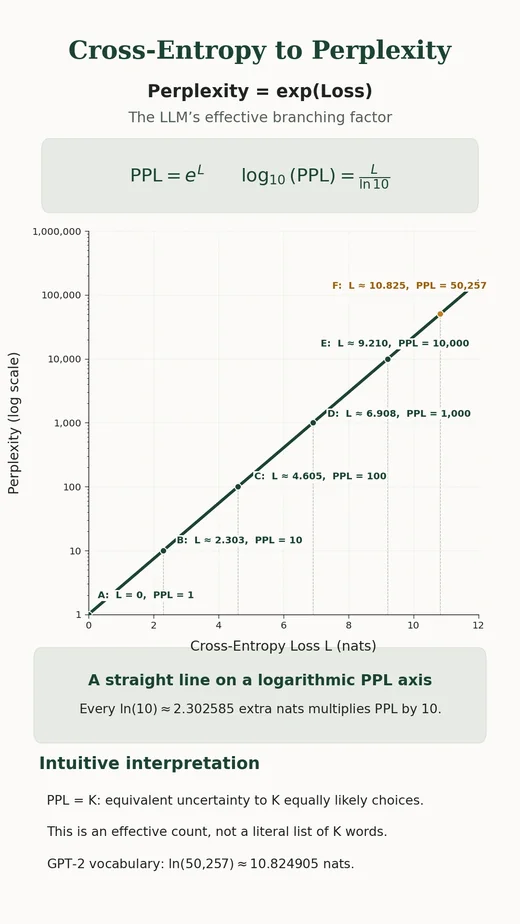 PICTURE 8 / 20How does cross entropy to perplexity branching factor operate mathematically within the overall LLM Loss Engine: Cross-Entropy & Perplexity?Build LLM From Scratch · LLM Loss Engine: Target Shifting, Cross-Entropy & Perplexity
Quantify and trace the mathematical mechanism of cross entropy to perplexity branching factor across layer dimensions and operations.
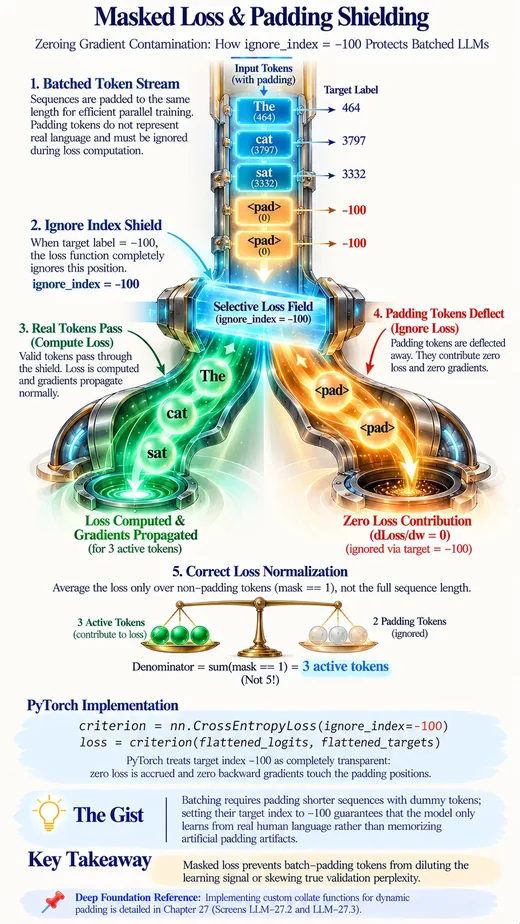 PICTURE 9 / 20How does masked loss with ignore index operate mathematically within the overall LLM Loss Engine: Cross-Entropy & Perplexity?Build LLM From Scratch · LLM Loss Engine: Target Shifting, Cross-Entropy & Perplexity
Quantify and trace the mathematical mechanism of masked loss with ignore index across layer dimensions and operations.
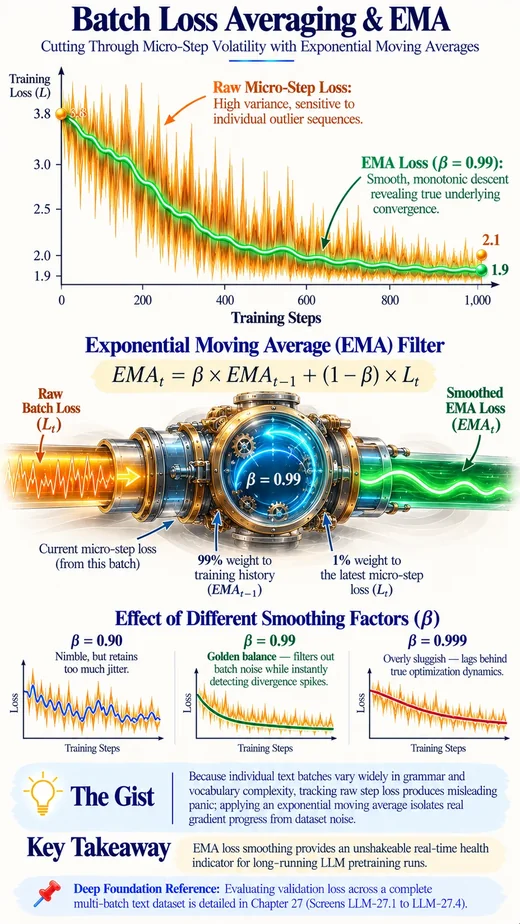 PICTURE 10 / 20How does batch loss averaging and exponential smoothing operate mathematically within the overall LLM Loss Engine: Cross-Entropy & Perplexity?Build LLM From Scratch · LLM Loss Engine: Target Shifting, Cross-Entropy & Perplexity
Quantify and trace the mathematical mechanism of batch loss averaging and exponential smoothing across layer dimensions and operations.
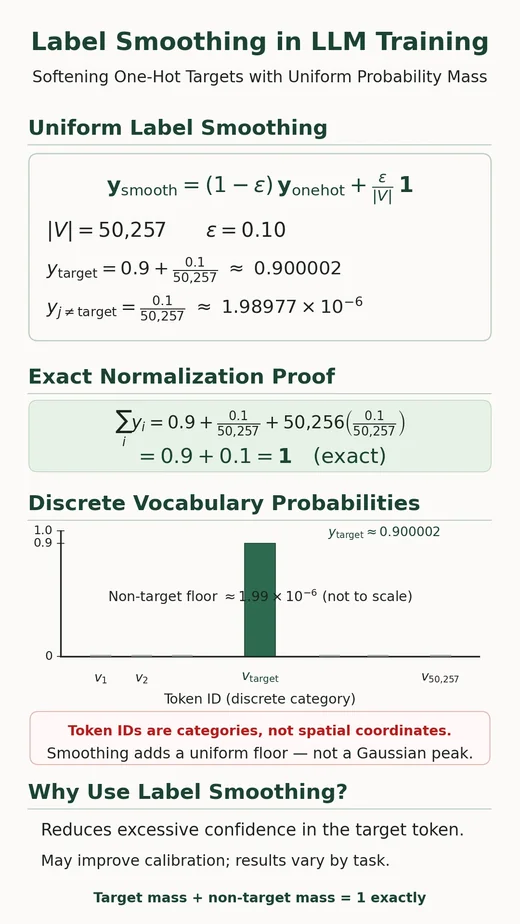 PICTURE 11 / 20How does label smoothing in cross entropy operate mathematically within the overall LLM Loss Engine: Cross-Entropy & Perplexity?Build LLM From Scratch · LLM Loss Engine: Target Shifting, Cross-Entropy & Perplexity
Quantify and trace the mathematical mechanism of label smoothing in cross entropy across layer dimensions and operations.
Lessons 9
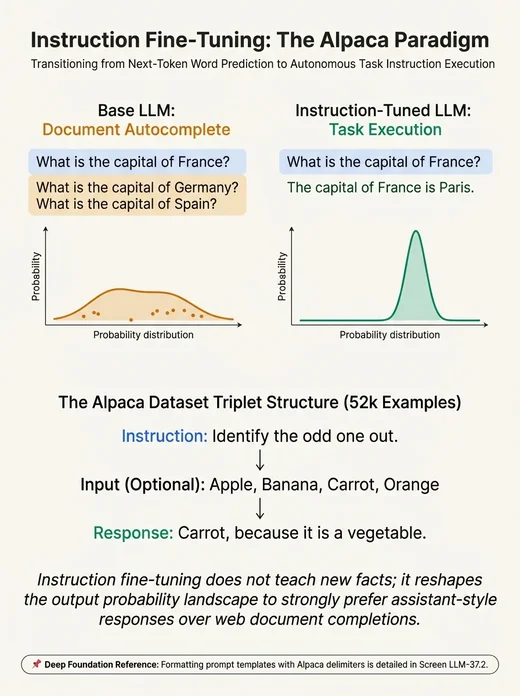 LESSONStanford Alpaca: Supervised Instruction Finetuning From ScratchBuild LLM From Scratch
Master the complete Stanford Alpaca instruction finetuning pipeline: parse 52,000 JSON records, implement structured prompt templates, execute dynamic batch collation with prompt loss shielding, run the SFT training loop with cosine warmup, and benchmark qualitative responses.
LESSONIntro to LLMBuild LLM From ScratchWhat core mathematical principle governs from task specific nlp to general purpose llms?
LESSONFour Stages Of Building LLMBuild LLM From ScratchWhat is the complete roadmap from a raw text file to a conversational AI assistant?
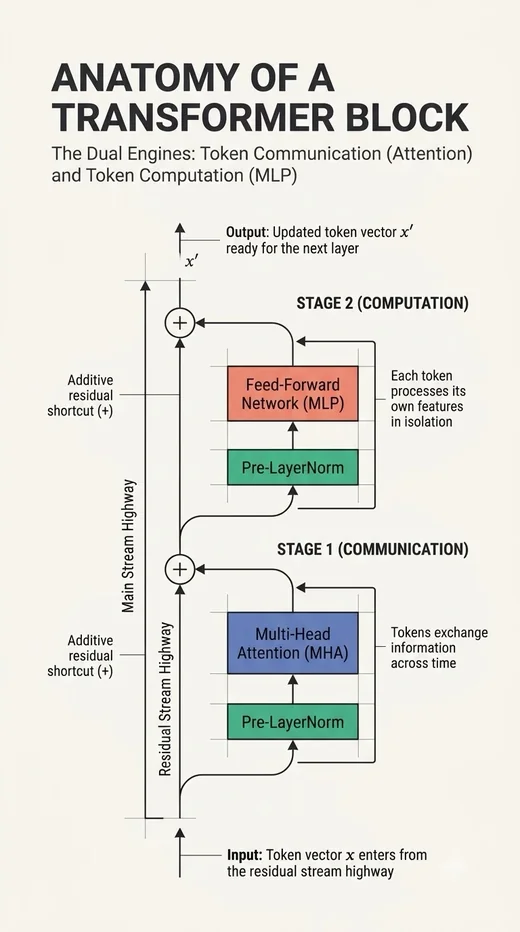 LESSONLLM ArchitectureBuild LLM From Scratch
How are Transformer blocks composed, stacked, and projected to predict next tokens?
LESSONLLM Loss Engine: Target Shifting, Cross-Entropy & PerplexityBuild LLM From ScratchHow do we mathematically quantify prediction error across billions of tokens, and how does cross-entropy loss translate directly into language perplexity?
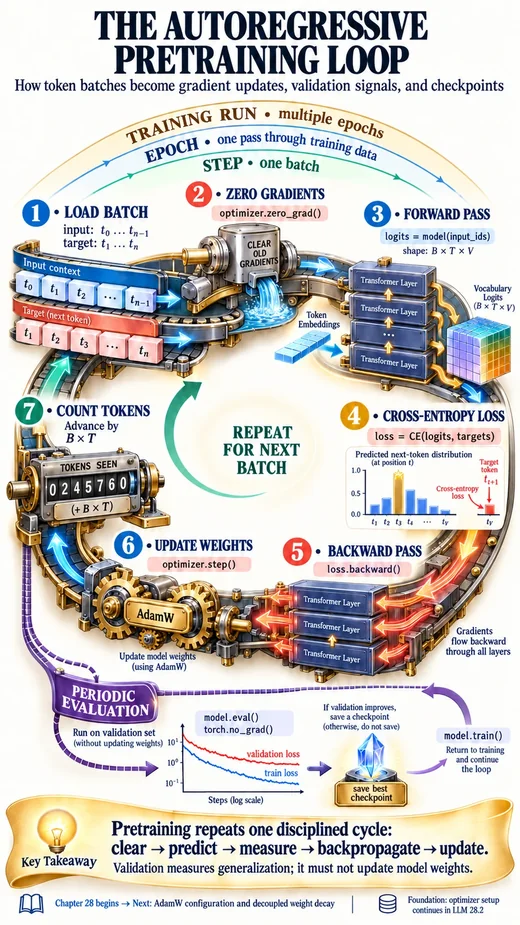 LESSONLLM Pretraining: Optimization Loops, Cosine Schedules & StabilityBuild LLM From Scratch
How do learning rate schedules, gradient clipping, and AdamW optimization integrate into a production pretraining loop that trains billions of parameters without loss spikes or divergence?
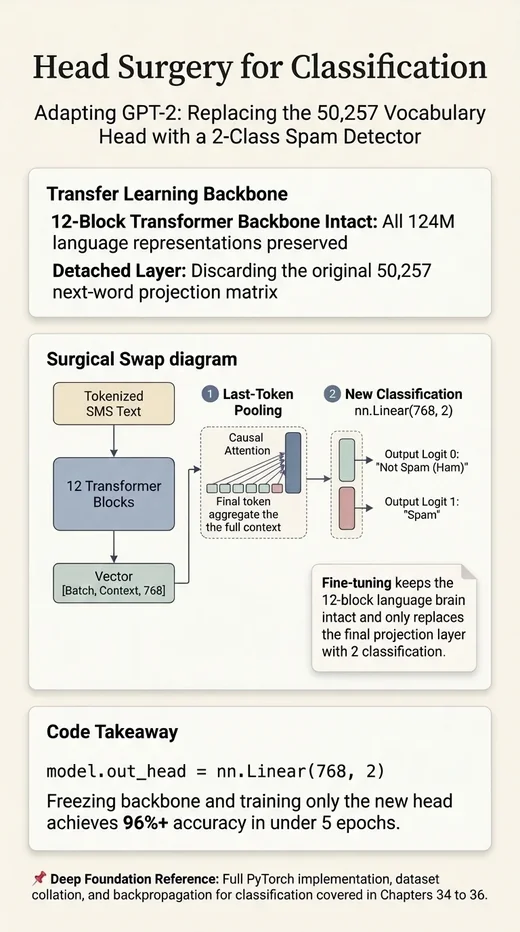 LESSONLlm Finetuning IntroBuild LLM From Scratch
How does head surgery classification replacement solve the underlying computational bottleneck?
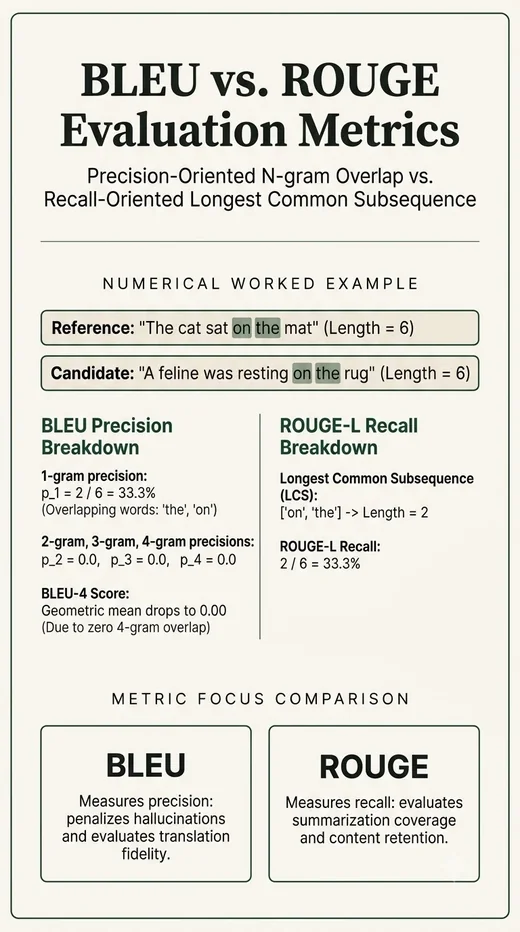 LESSONFinetuned LLM Evaluation: Metrics, Hierarchy, and BenchmarkingBuild LLM From Scratch
Why do traditional n-gram matching metrics like BLEU and ROUGE fail to fully capture generative LLM quality, and how do precision and recall trade off mathematically?
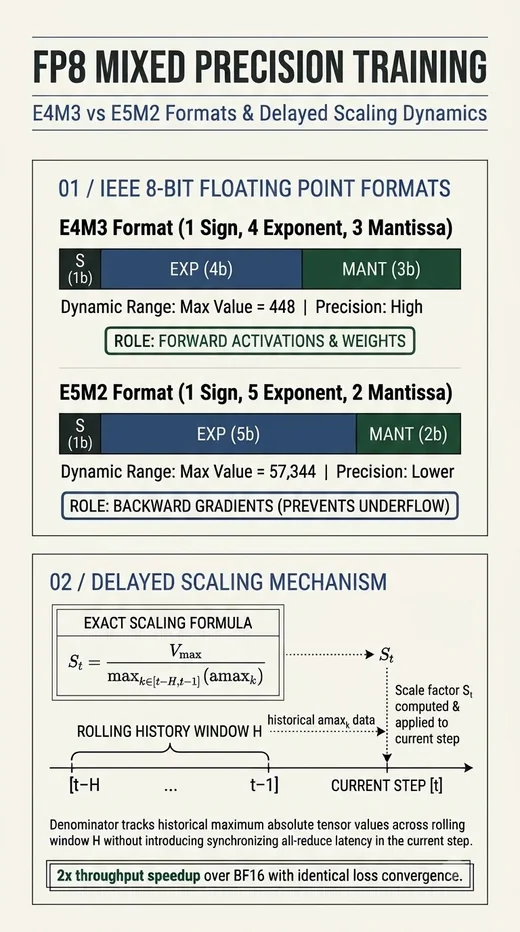 LESSONFrontier Scaling and Capstone: FP8 Precision, Mixture of Depths, NIAH, and Unified LLM ArchitectureBuild LLM From Scratch
How does 8-bit floating point training double GPU GEMM throughput while preventing gradient underflow via delayed scaling?