Build SLM From Scratch
Small Language Models on edge devices. Compute-optimal scaling, the Chinchilla law, and TinyStories synthetic data.
The cutting-edge frontier of efficient AI: run high-reasoning language models directly on local hardware.
- 7
- lessons
- 83
- visual explanations
- 1
- chapters
Build SLM From Scratch
Chinchilla scaling laws, parameter spectra, and synthetic data strategies.
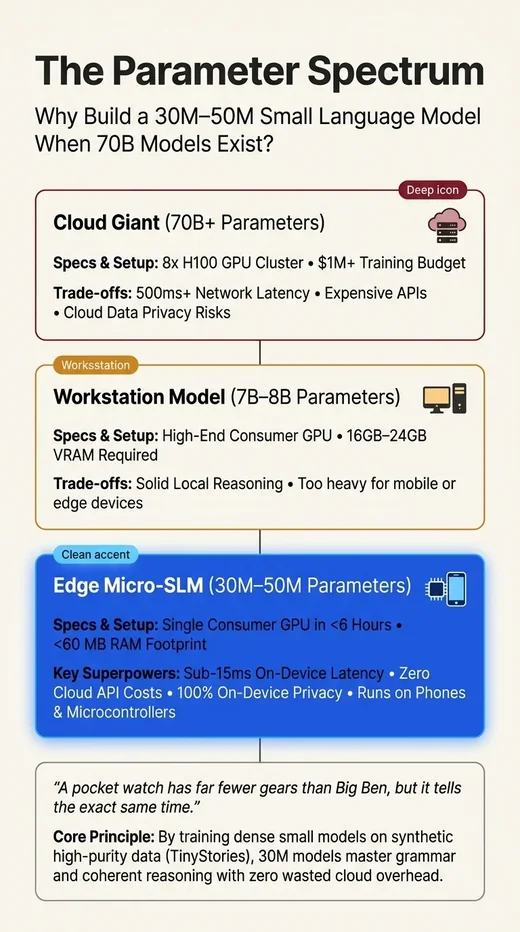
What core mathematical principle governs the parameter spectrum cloud vs edge micro slm?
Open lesson →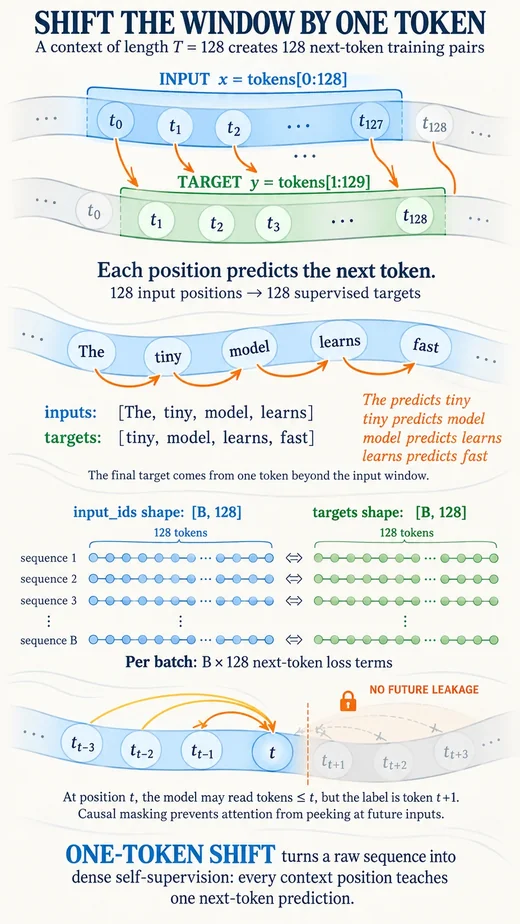
How do modern Small Language Models redesign self-attention and normalization to fit high-throughput reasoning onto battery-constrained mobile and edge NPUs?
Open lesson →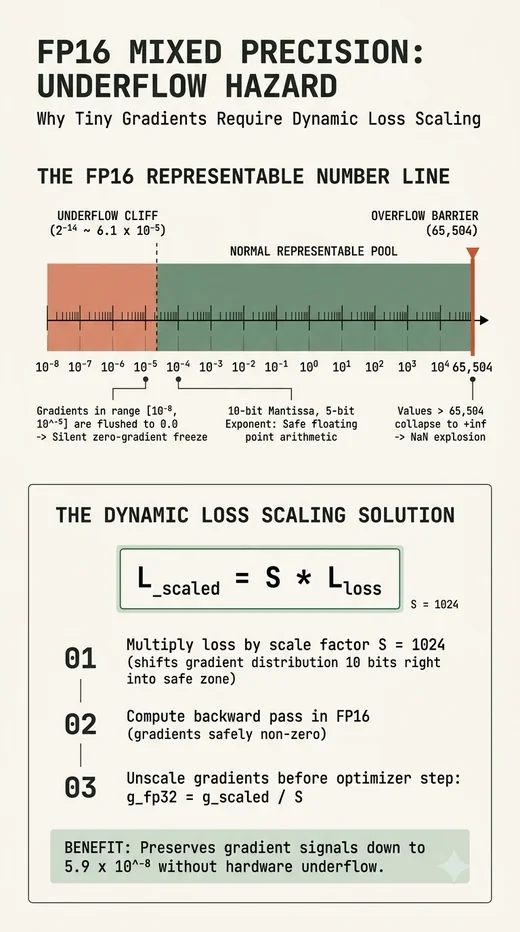
How do we train Small Language Models on modest GPU hardware using mixed-precision FP16/BF16 and gradient accumulation without numerical underflow or throughput bottlenecks?
Open lesson →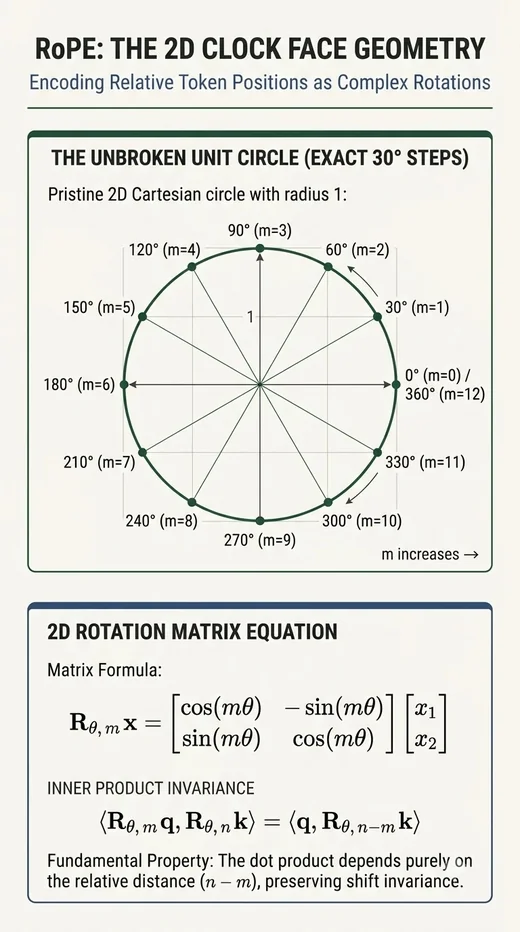
How do 2D clock-face rotations encode relative token positions directly into complex attention inner products?
Open lesson →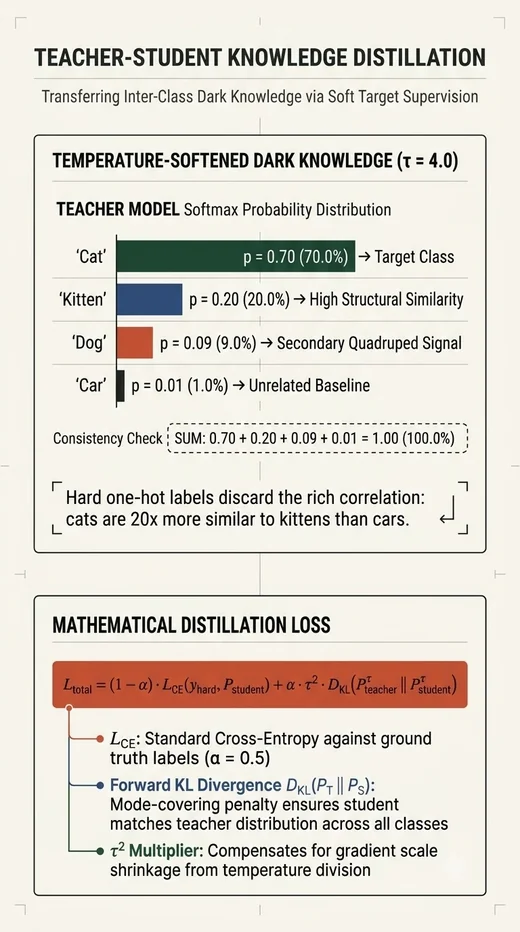
How do we compress a multi-billion parameter model into a compact footprint that runs smoothly on a phone NPU using knowledge distillation, pruning, and 4-bit quantization?
Open lesson →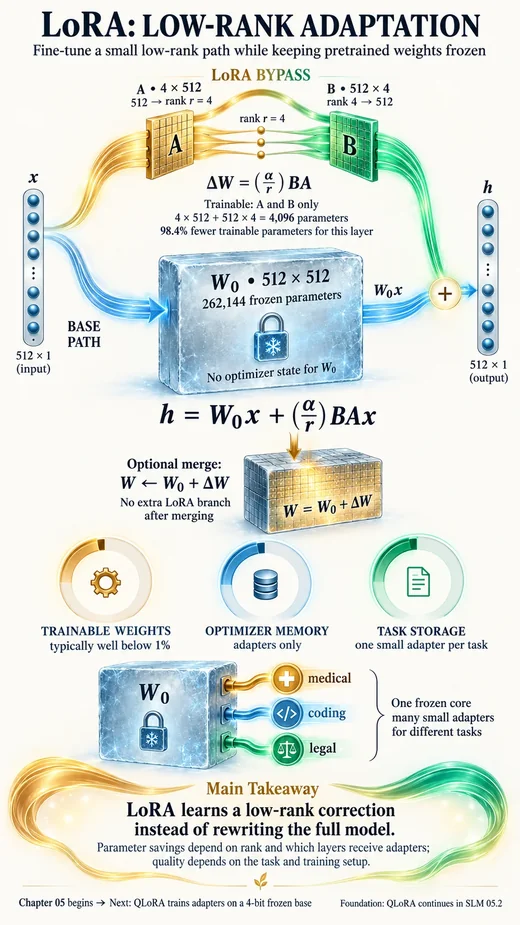
How do low-rank matrix decomposition (LoRA) and 4-bit NormalFloat quantization (QLoRA) enable fine-tuning on consumer hardware, and how is the KV cache optimized on mobile devices?
Open lesson →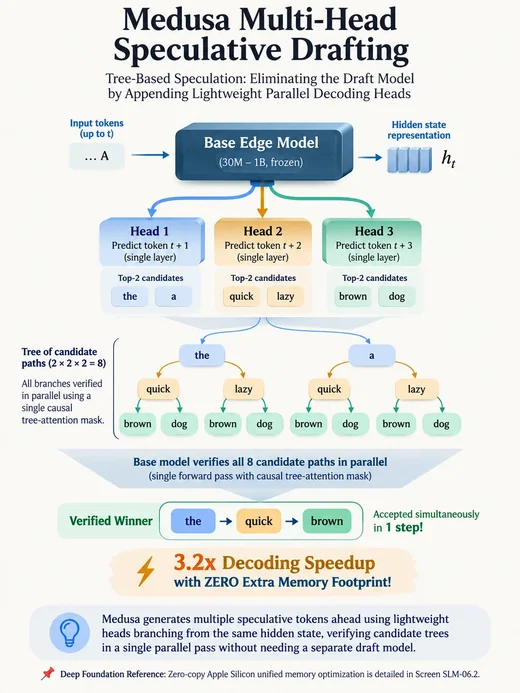
How do multiple speculative decoding heads (Medusa), Apple Silicon unified zero-copy memory, on-device voice streaming, and private local RAG unite into a complete edge AI application?
Open lesson →