Build LLM From Scratch
From tokenization to pretraining: verified visual architecture screens.
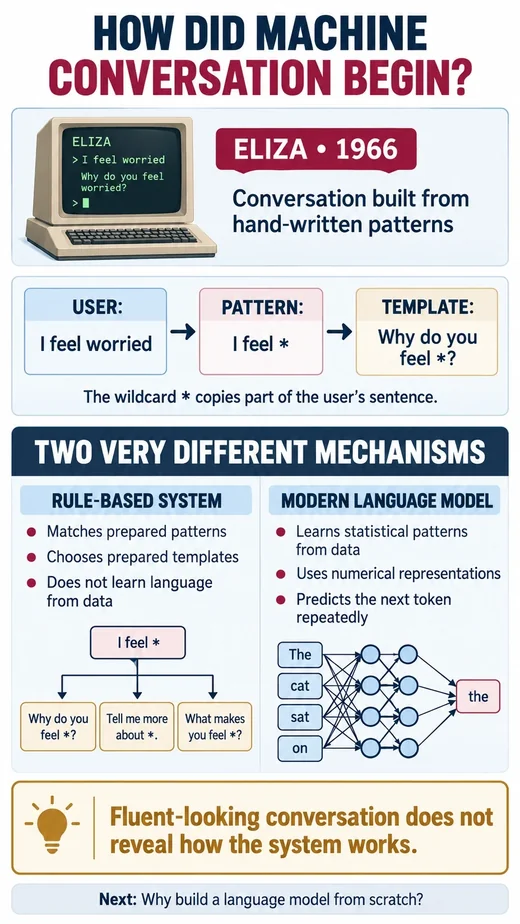
How did machine conversation begin, and how does ELIZA differ from a modern language model?
Open lesson →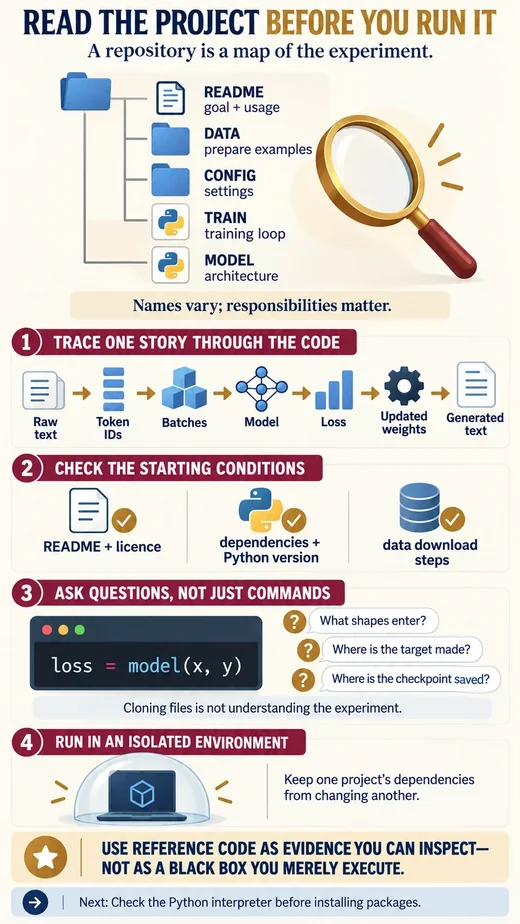
What core mathematical principle governs read the project before you run it?
Open lesson →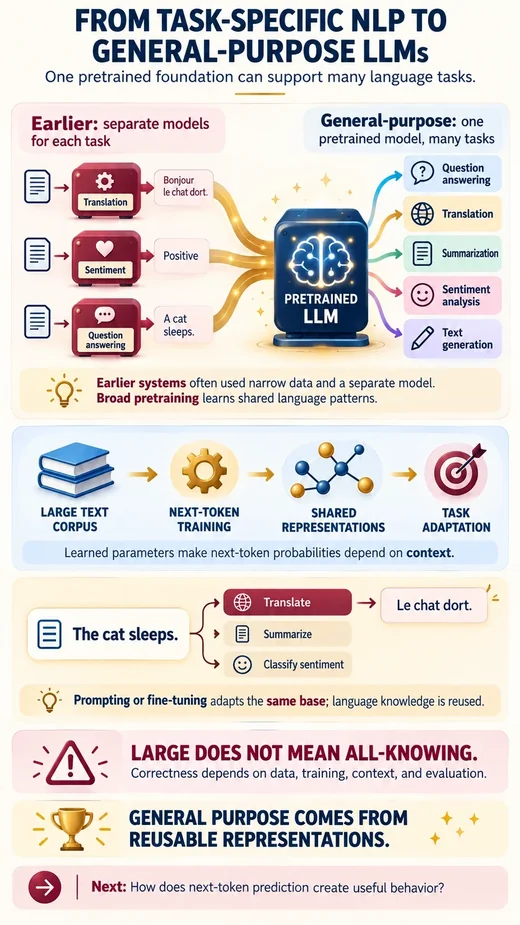
What core mathematical principle governs from task specific nlp to general purpose llms?
Open lesson →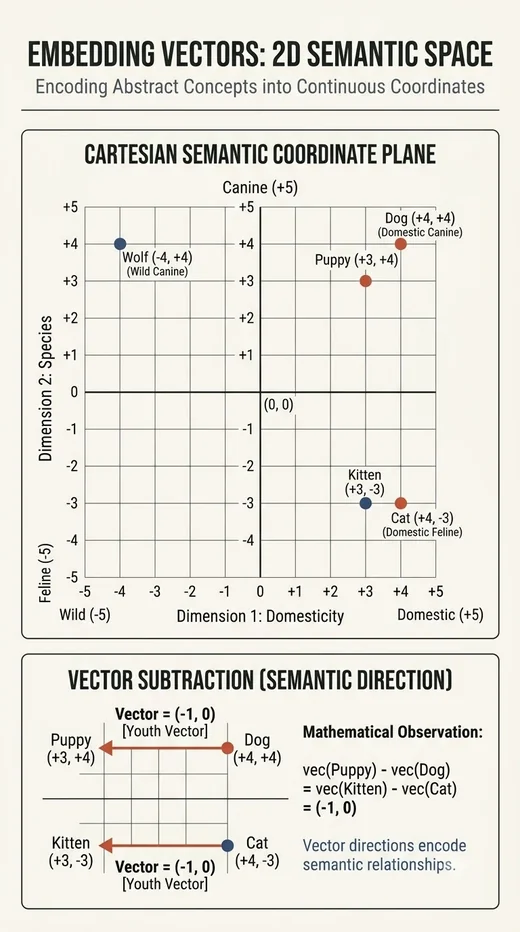
How do discrete token identifiers translate into continuous vector embeddings along high-dimensional semantic axes?
Open lesson →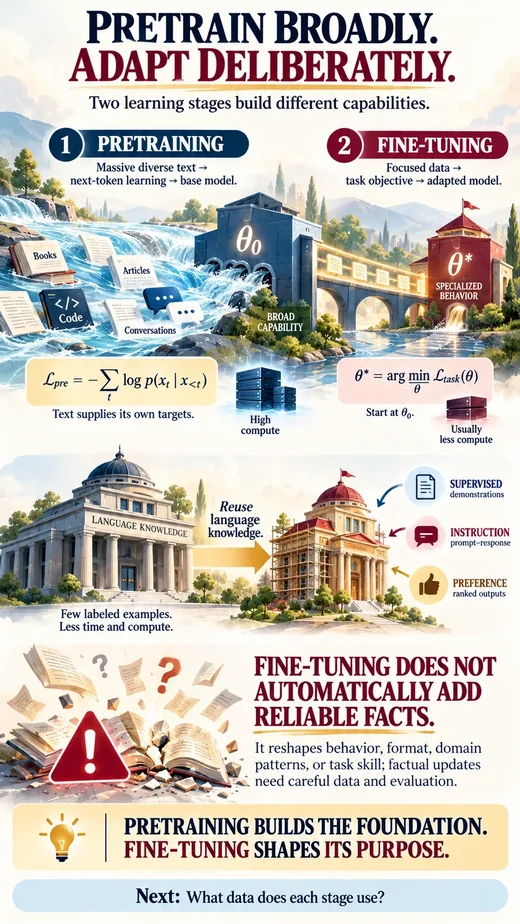
Why is the lifecycle of an LLM fundamentally separated into self-supervised pretraining and supervised fine-tuning?
Open lesson →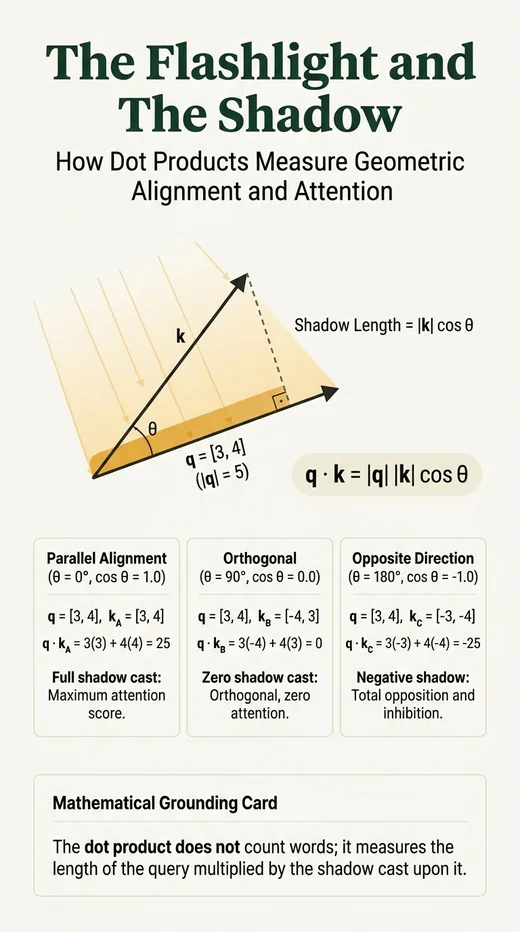
How do query-key projections, softmax budgeting, and multi-head subspace synthesis route contextual information across tokens?
Open lesson →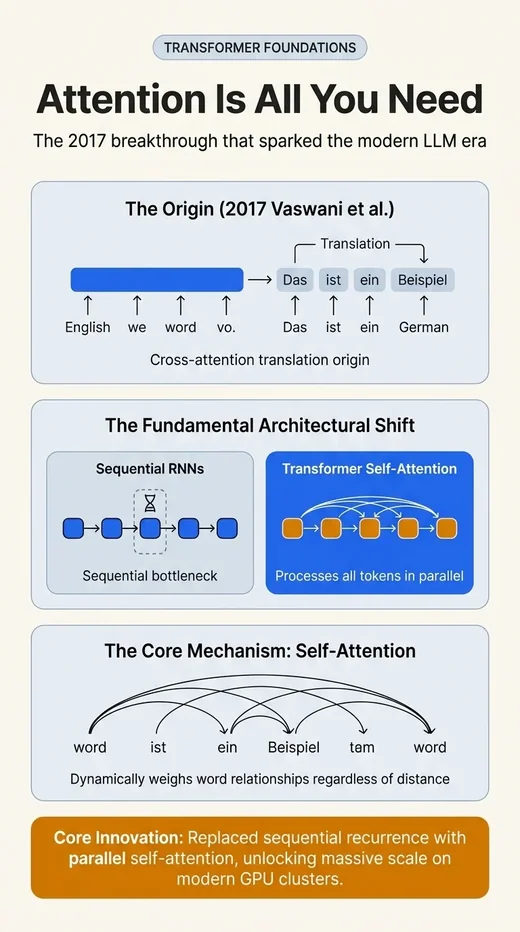
What core breakthrough did Attention Is All You Need introduce?
Open lesson →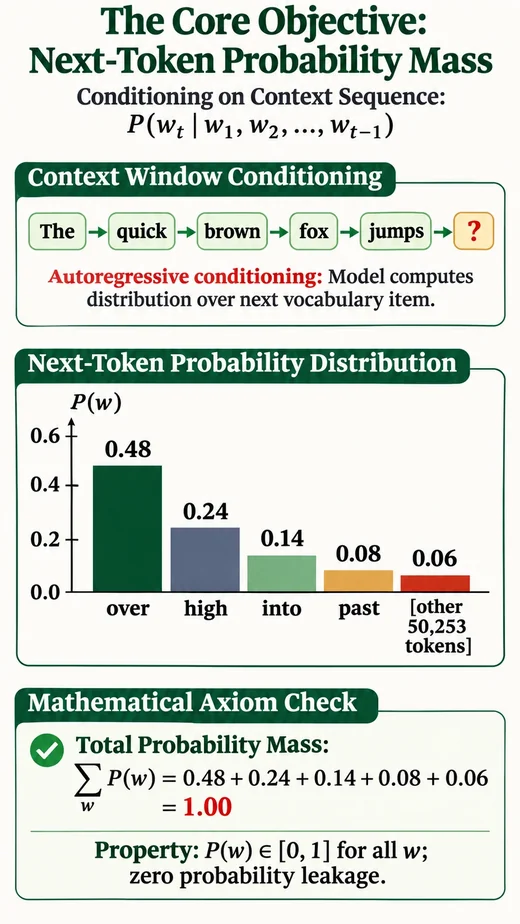
How does minimizing cross-entropy on next-token prediction induce high-level reasoning, code synthesis, and world models?
Open lesson →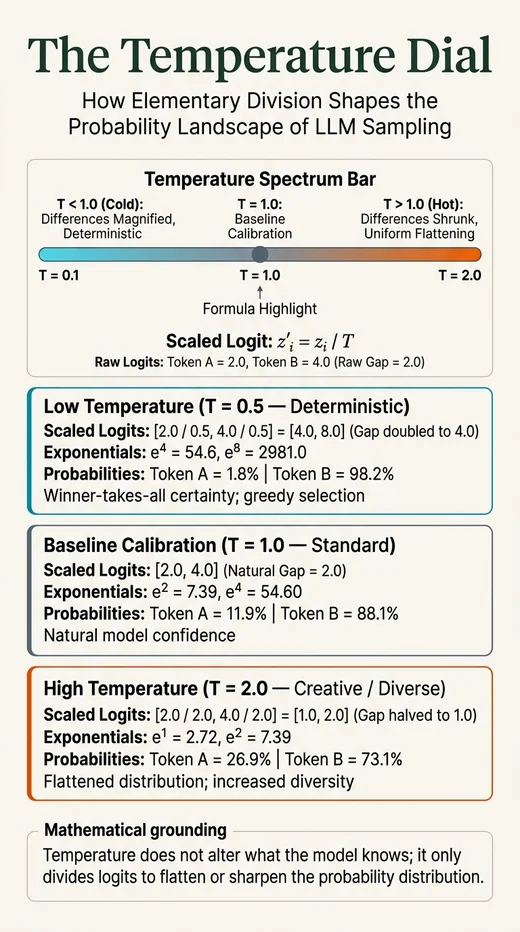
How do numerical stability shields, temperature scaling, and multinomial sampling steer the autoregressive pretraining engine?
Open lesson →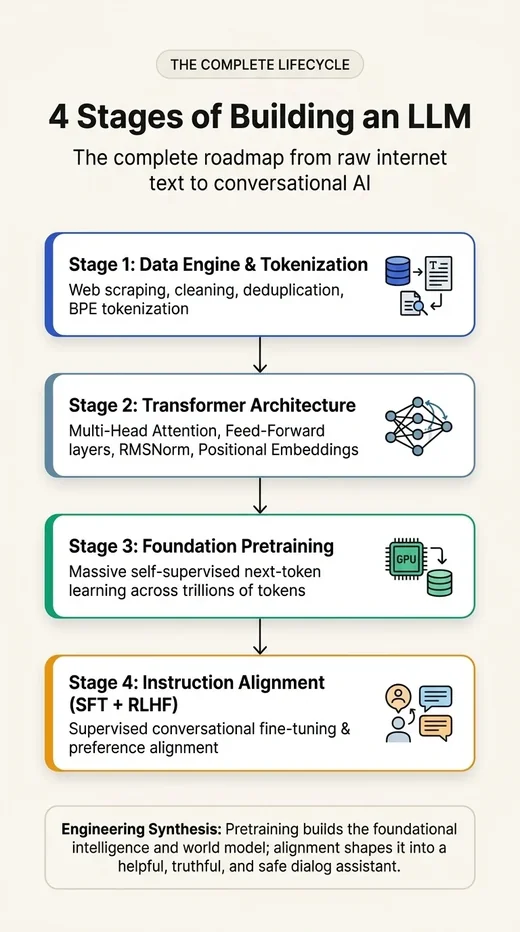
What is the complete roadmap from a raw text file to a conversational AI assistant?
Open lesson →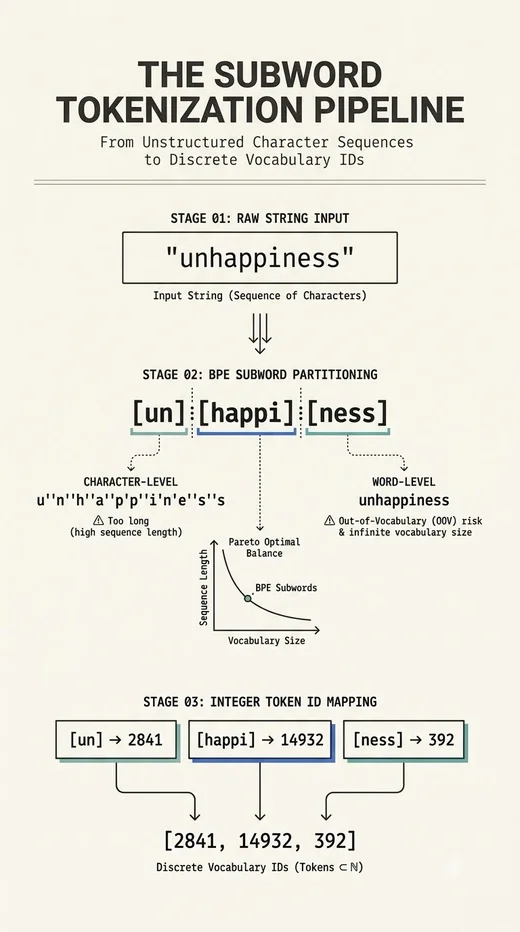
How does the tokenization pipeline transform raw Unicode text into integer tensors for neural network consumption?
Open lesson →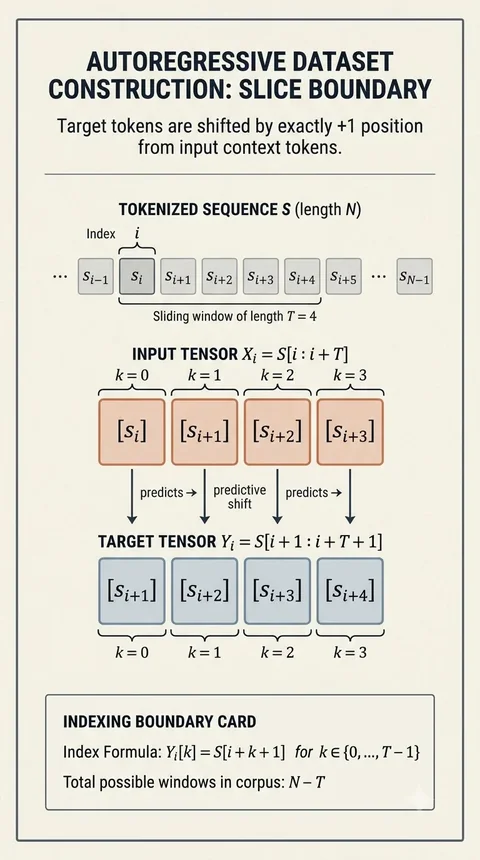
How does continuous text turn into supervised training targets for LLM pretraining?
Open lesson →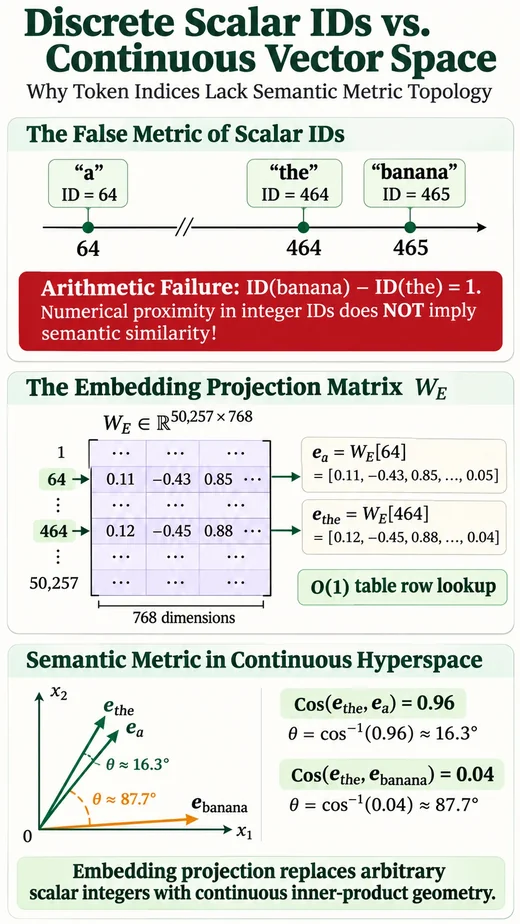
What core mathematical principle governs bridge token ids versus learned values?
Open lesson →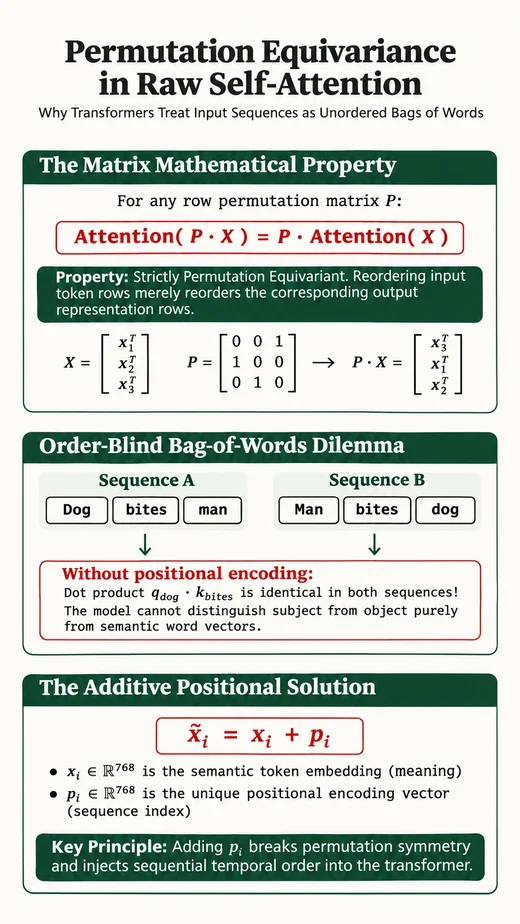
Why does standard self-attention treat 'dog bites man' and 'man bites dog' identically without positional encodings?
Open lesson →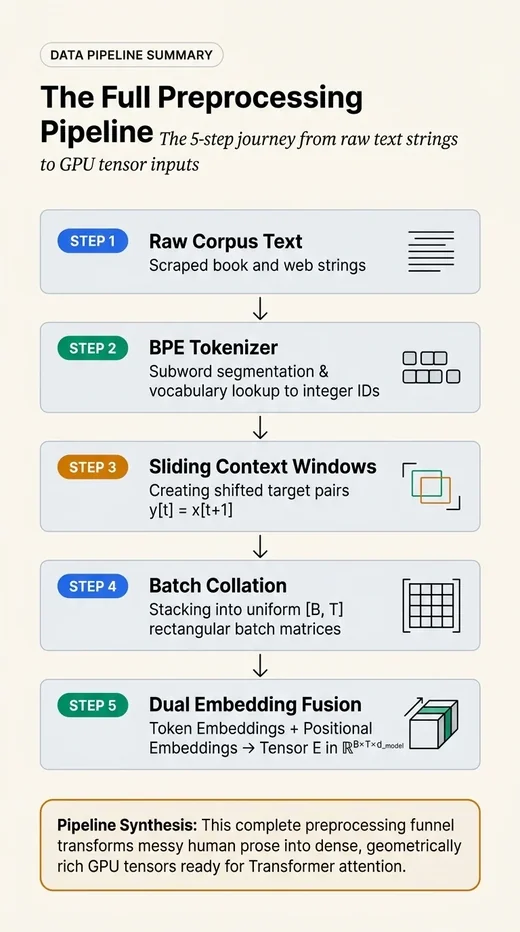
What is the complete journey from raw text strings to GPU tensor inputs?
Open lesson →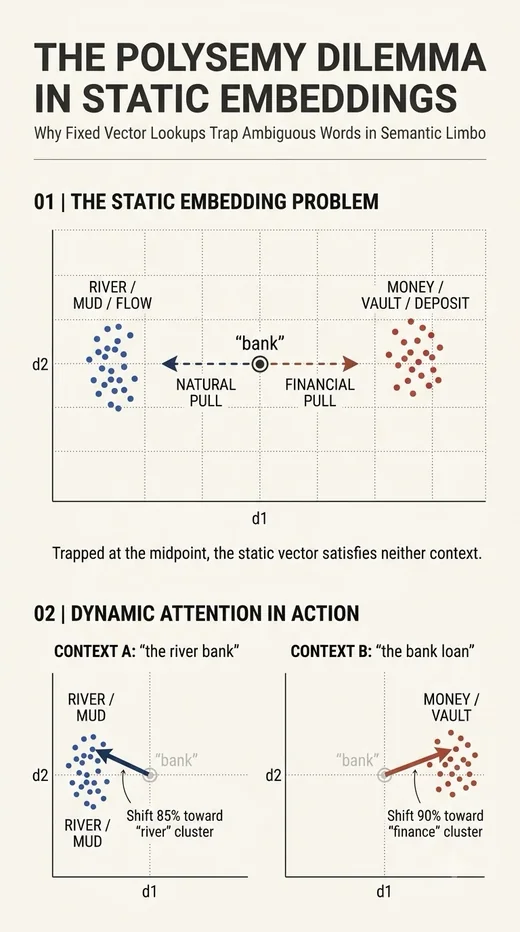
Why are static word embeddings insufficient for words with multiple meanings, and how does attention dynamically contextualize them?
Open lesson →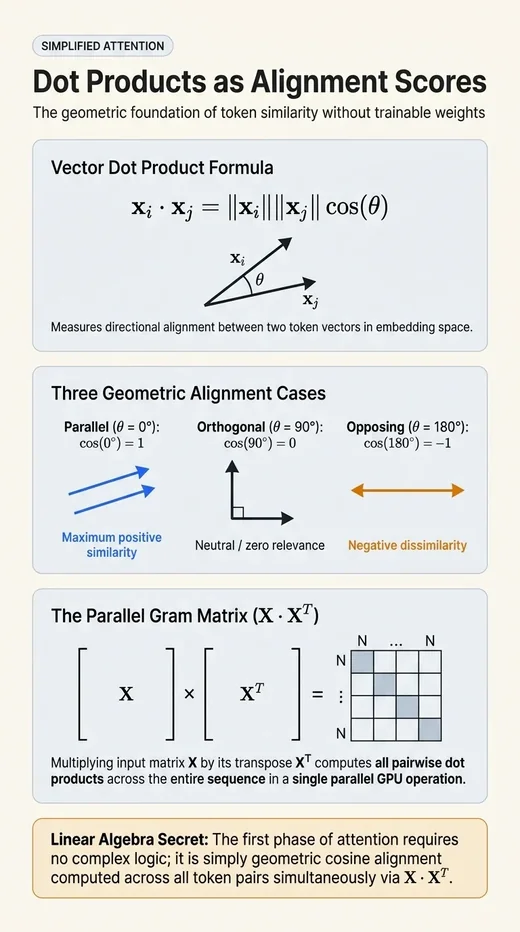
What is the simplest mathematical formulation of self-attention without trainable weights?
Open lesson →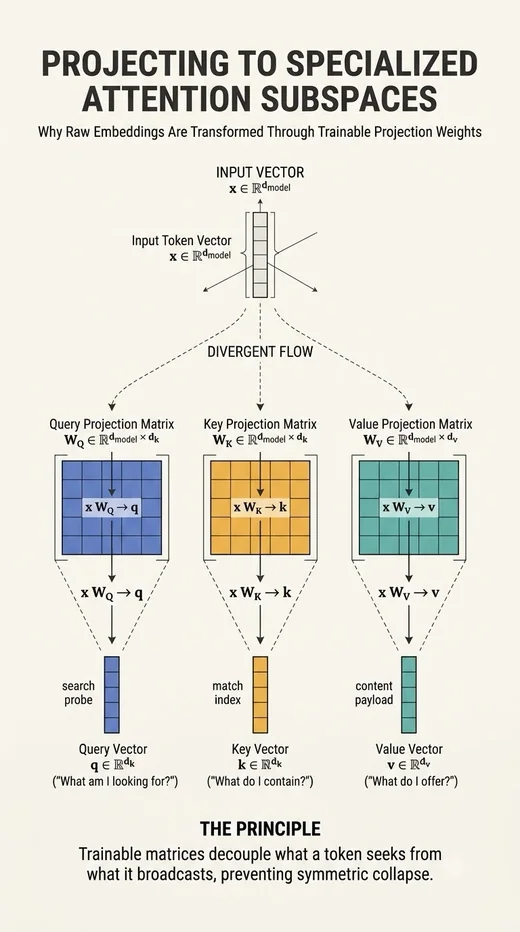
Why cannot self-attention just use raw input vectors, and what are Queries, Keys, and Values?
Open lesson →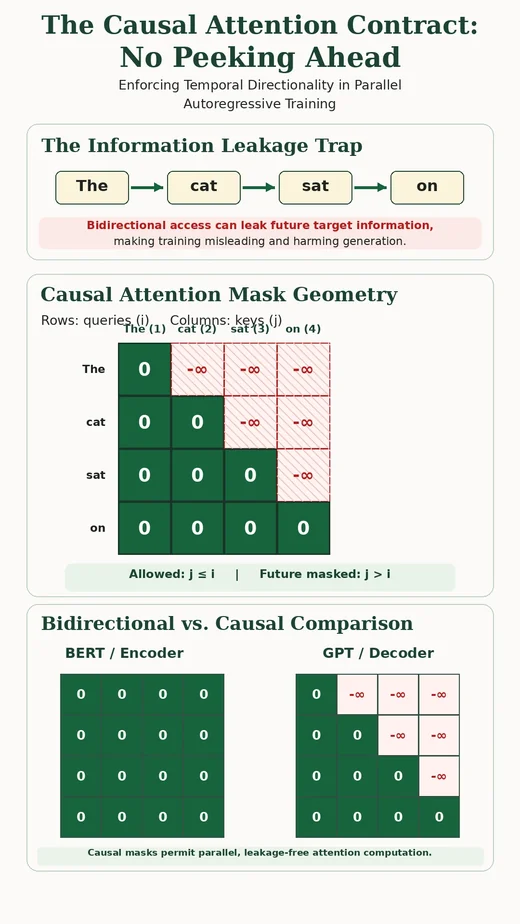
Why must generative LLMs conceal future token positions, and how does causal masking enforce autoregression?
Open lesson →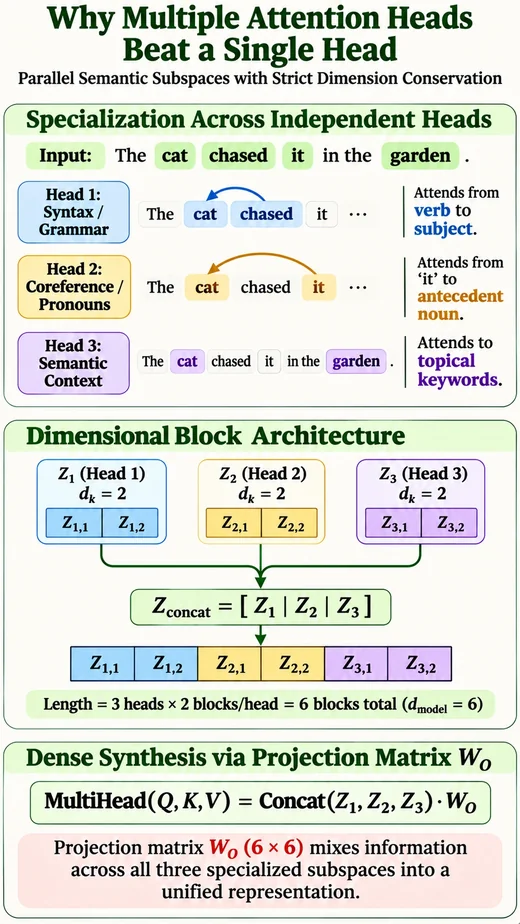
Why are multiple attention heads better than one single head, and how is the embedding dimension partitioned?
Open lesson →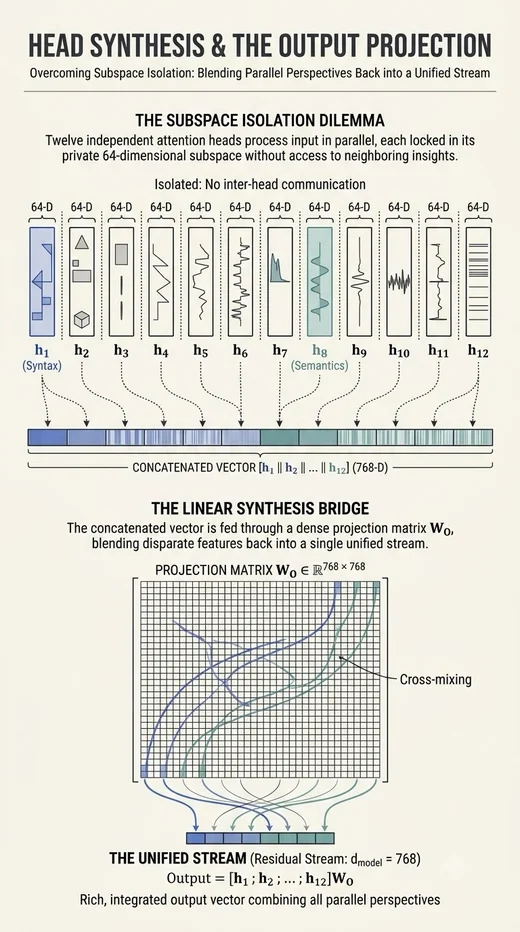
How do multiple head outputs recombine, and how do 4D tensors flow through multi-head attention?
Open lesson →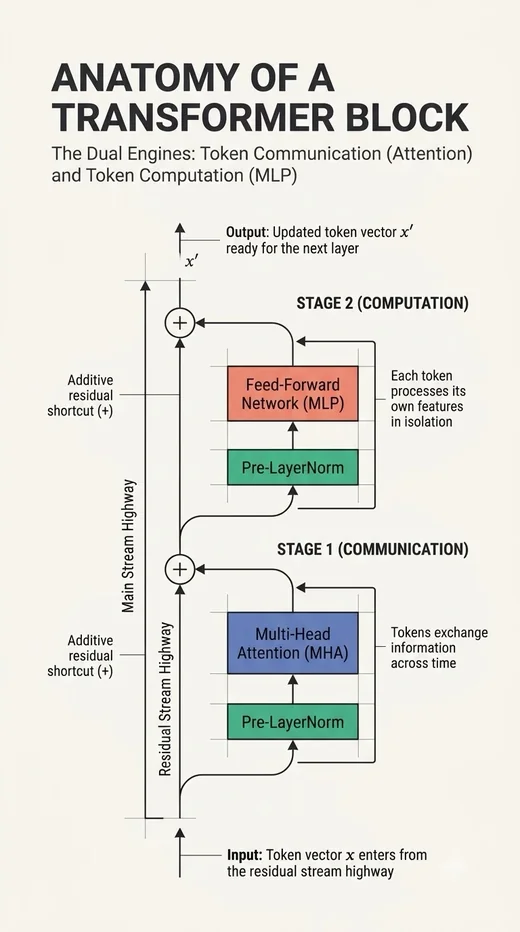
How are Transformer blocks composed, stacked, and projected to predict next tokens?
Open lesson →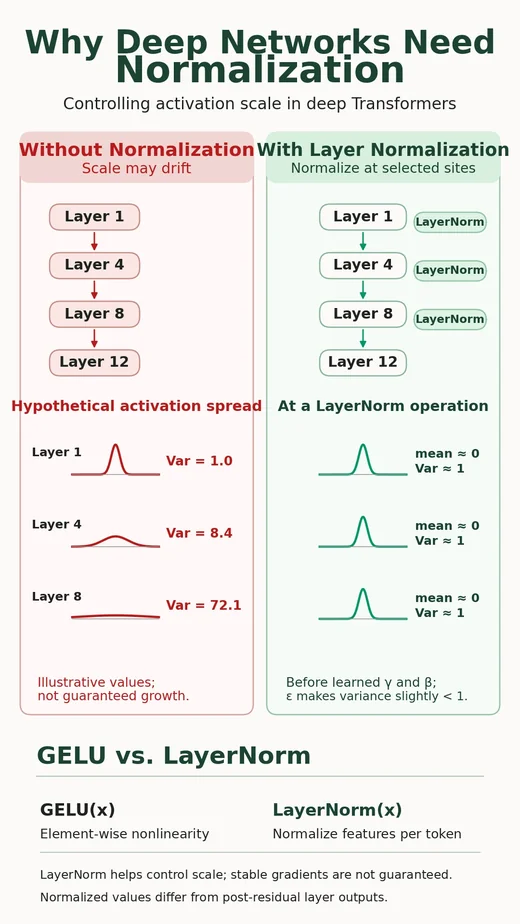
Why do deep transformer networks suffer from internal covariate shift and exploding/vanishing gradients without normalization?
Open lesson →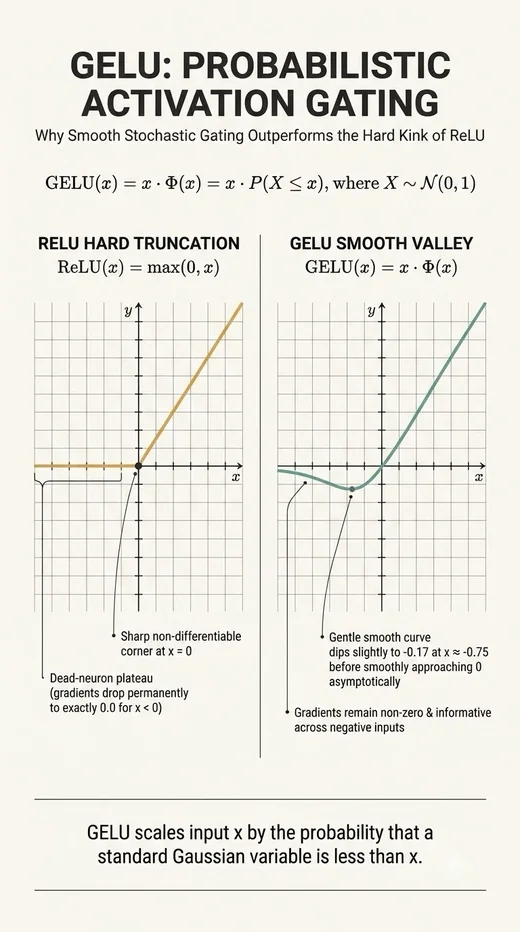
How does the Gaussian Error Linear Unit (GELU) introduce probabilistic gating compared to deterministic ReLU?
Open lesson →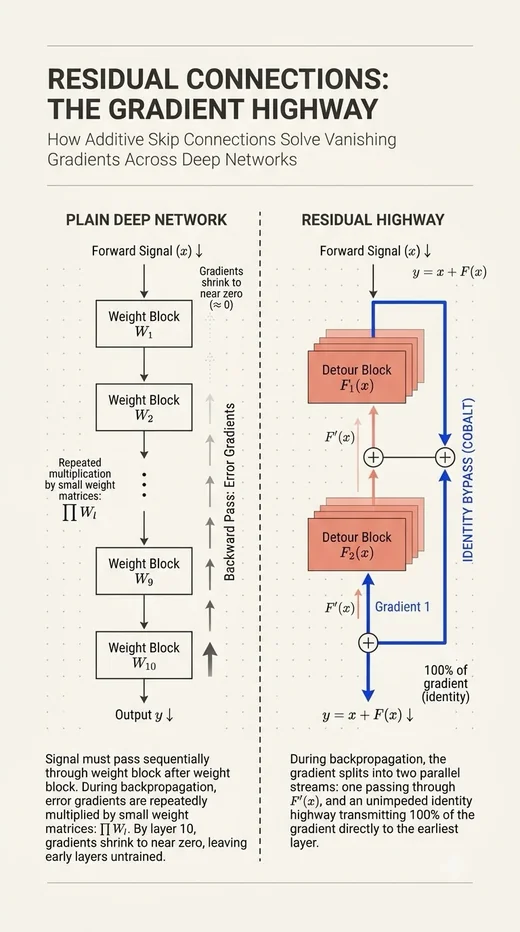
How do residual shortcut connections create an unhindered gradient highway across deep transformer layers?
Open lesson →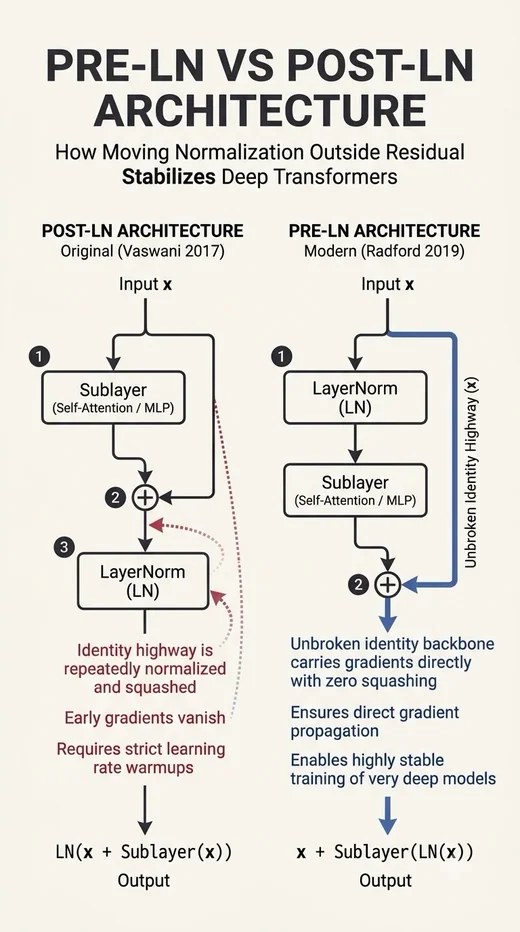
How are all sub-components assembled into a Pre-LN Transformer Block, and what is its shape ledger?
Open lesson →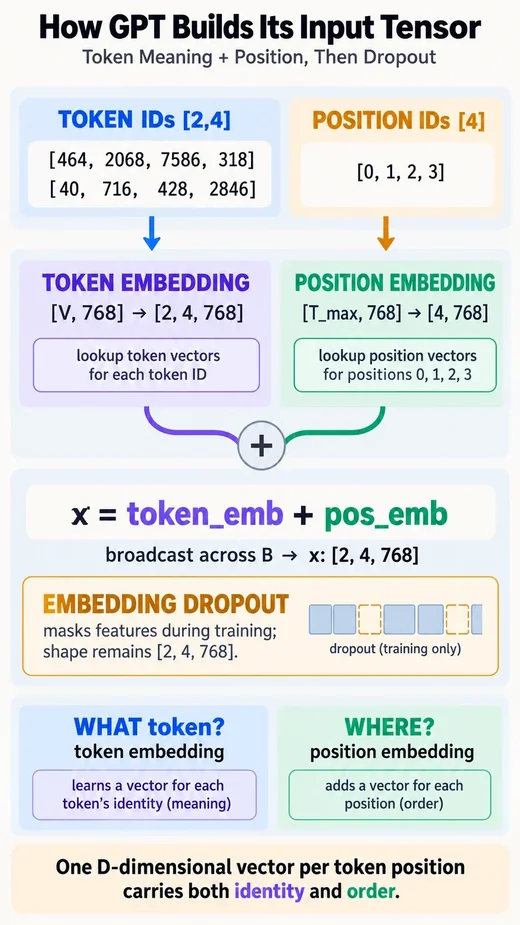
How does GPT-2 (124M) construct its unified input tensor from discrete token IDs and positional embeddings?
Open lesson →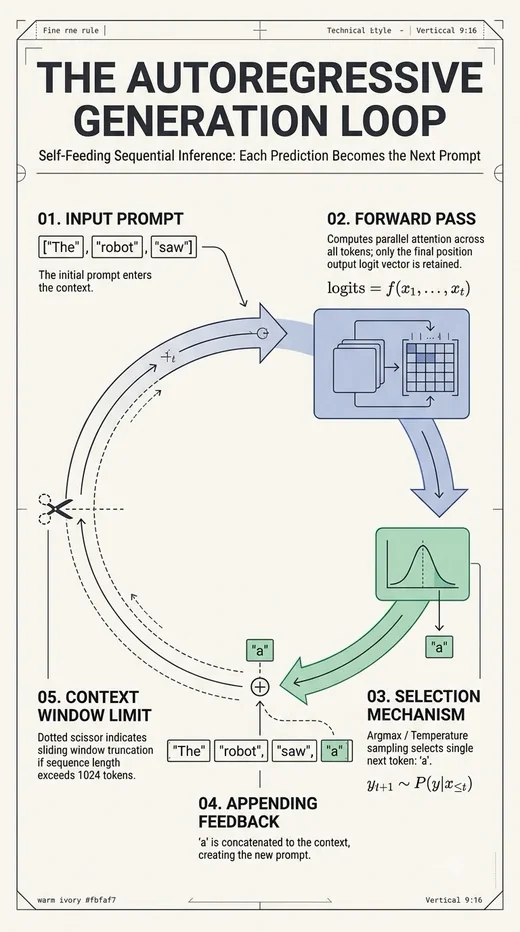
How do raw 3D unnormalized logits from the final transformer layer get converted into coherent, auto-regressively generated natural language tokens?
Open lesson →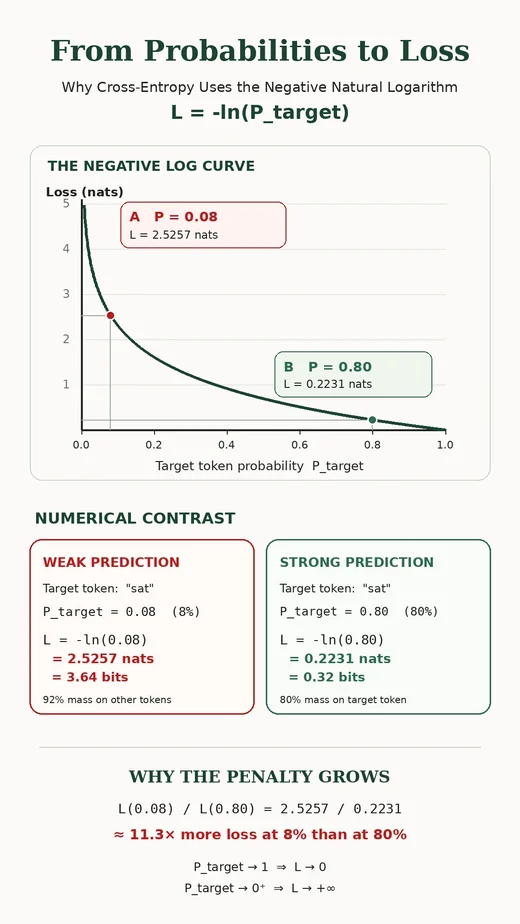
How do we mathematically quantify prediction error across billions of tokens, and how does cross-entropy loss translate directly into language perplexity?
Open lesson →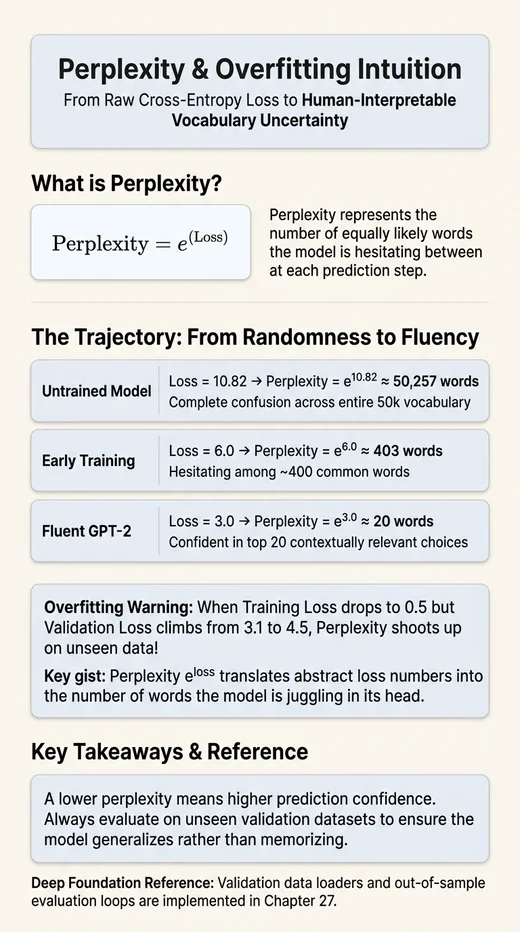
How does perplexity and overfitting intuition solve the underlying computational bottleneck?
Open lesson →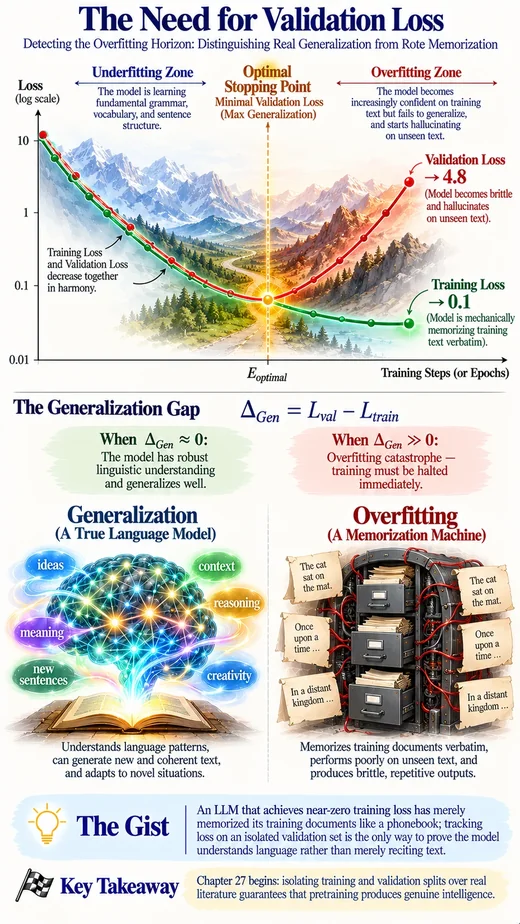
How do we detect when a language model stops learning linguistic grammar and starts memorizing training noise, and how do train/validation splits prevent overfitting?
Open lesson →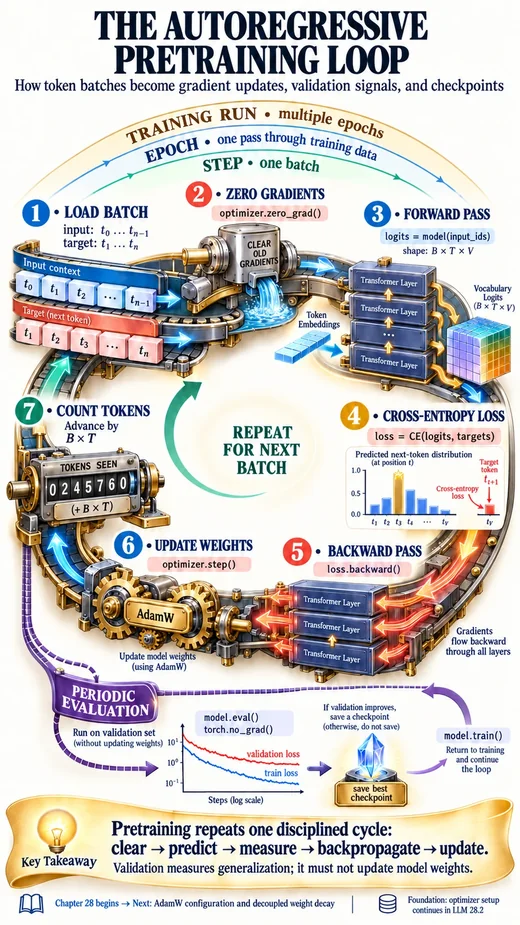
How do learning rate schedules, gradient clipping, and AdamW optimization integrate into a production pretraining loop that trains billions of parameters without loss spikes or divergence?
Open lesson →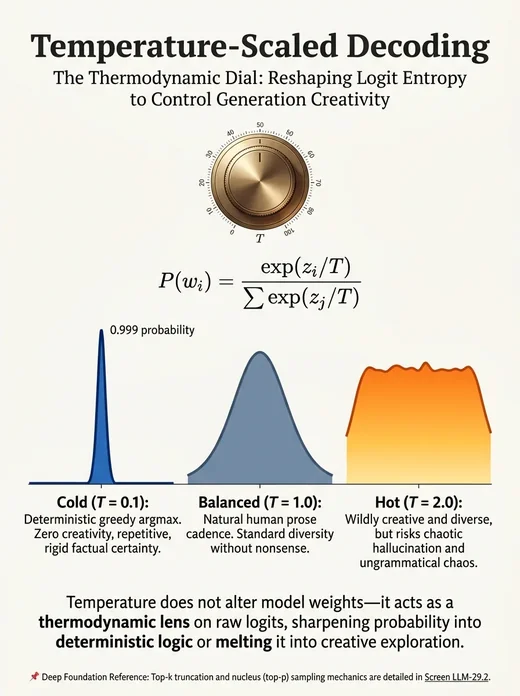
How do temperature scaling, top-k filtering, and nucleus (top-p) sampling mathematically reshape probability distributions to eliminate repetitive loops and hallucinated tail tokens?
Open lesson →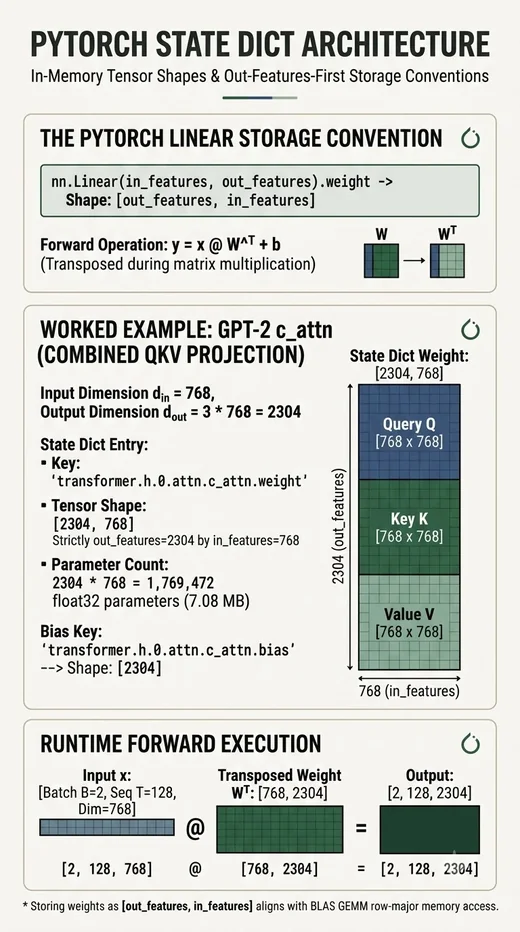
How do billions of floating-point weights and optimizer moments get safely serialized to disk without memory duplication or arbitrary code execution vulnerabilities?
Open lesson →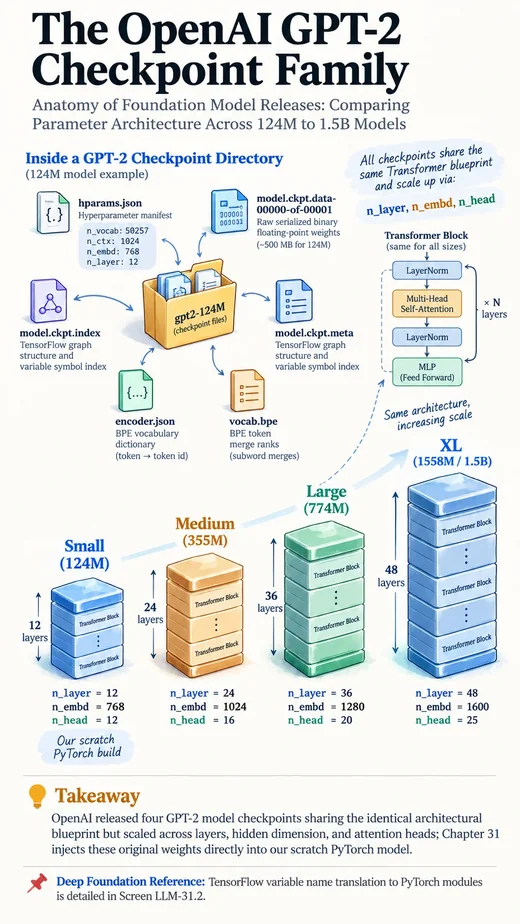
How do official TensorFlow-format GPT-2 model weights from OpenAI get downloaded, mapped, transposed, and verified byte-for-byte inside a from-scratch PyTorch architecture?
Open lesson →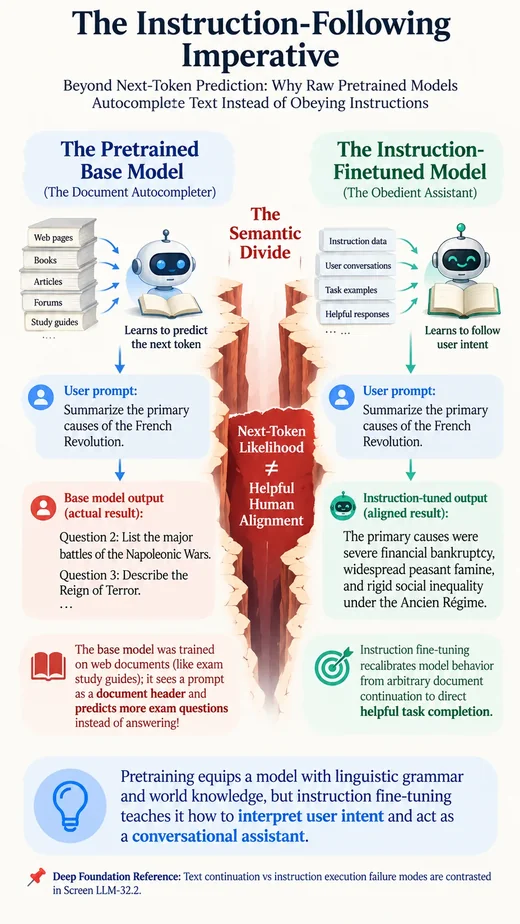
Why does a base pretrained language model fail to answer simple questions, and how does supervised instruction finetuning (SFT) transform a raw document completer into a helpful, obedient AI assistant?
Open lesson →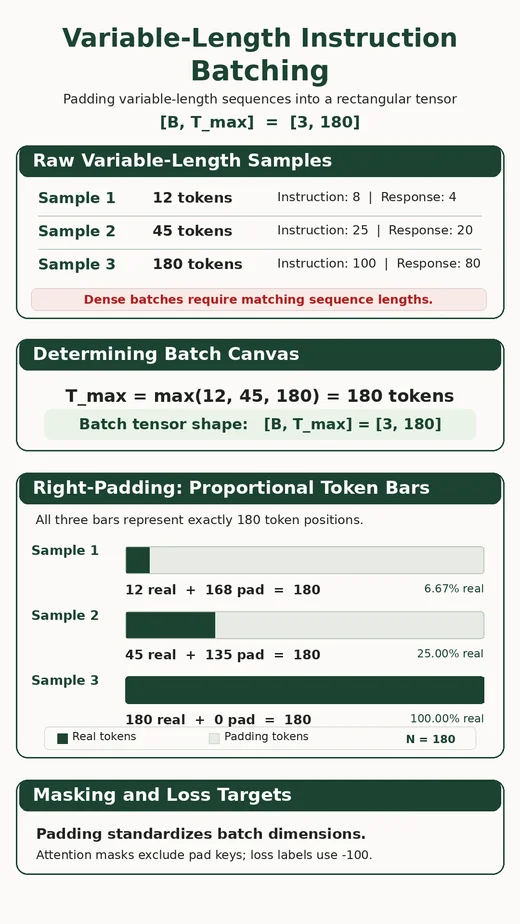
How do variable-length prompt-response pairs get transformed into rectangular batches without computing loss on padding or prompt tokens?
Open lesson →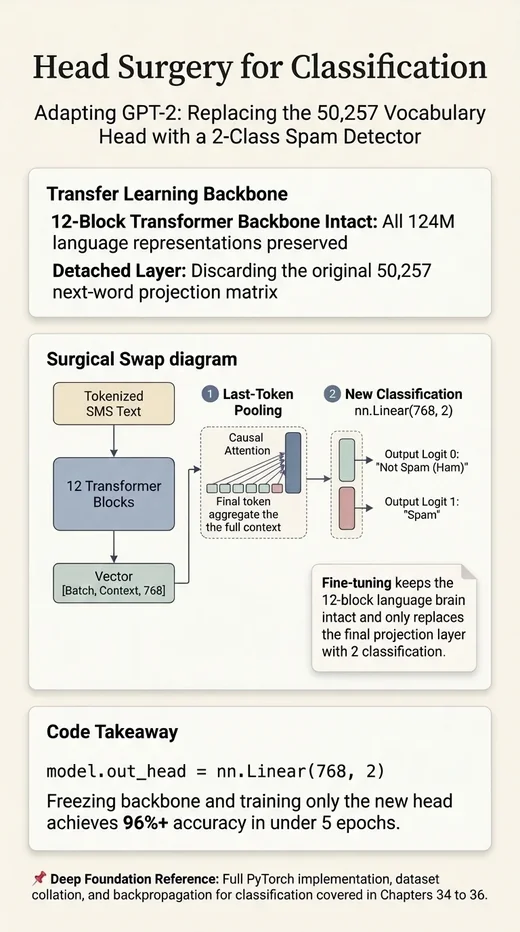
How does head surgery classification replacement solve the underlying computational bottleneck?
Open lesson →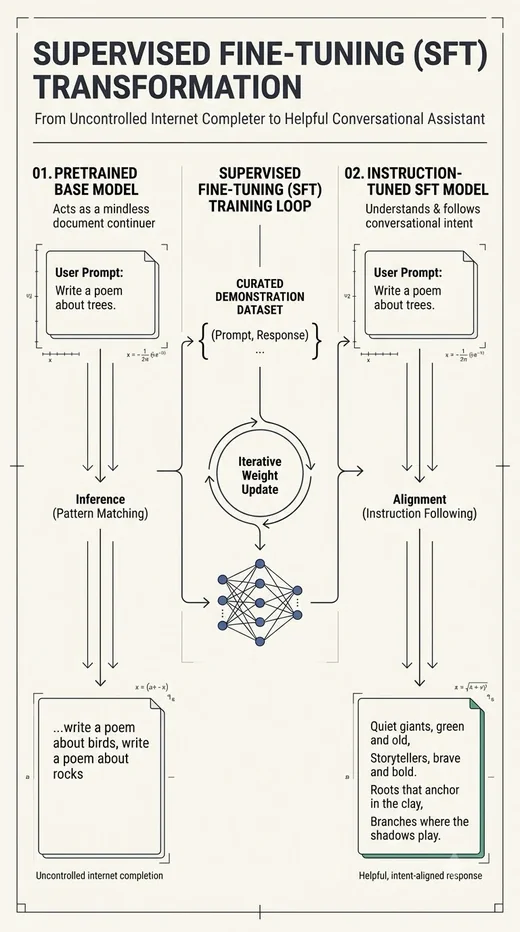
How does the full-parameter supervised finetuning loop orchestrate forward passes, masked loss computation, gradient accumulation, and checkpoint saving?
Open lesson →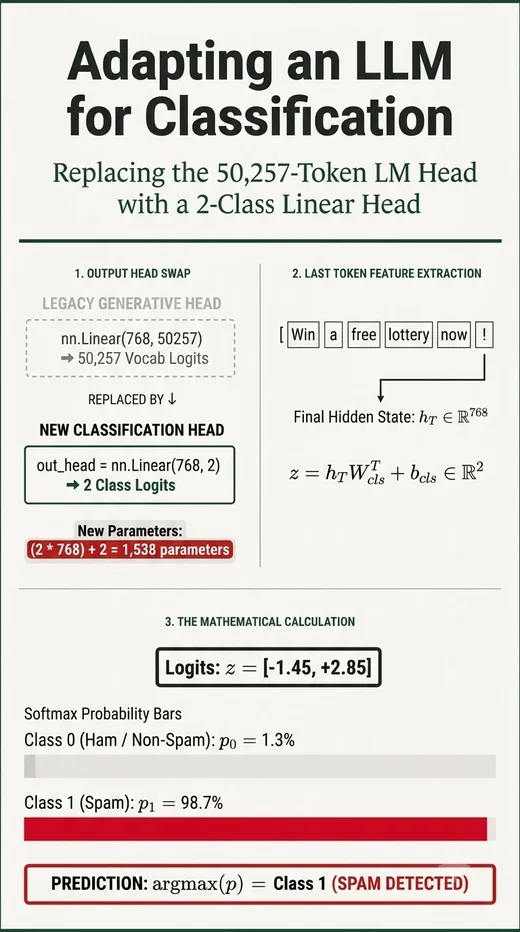
How are generative autoregressive transformers repurposed into high-precision discrete classifiers through linear head surgery and selective parameter freezing?
Open lesson →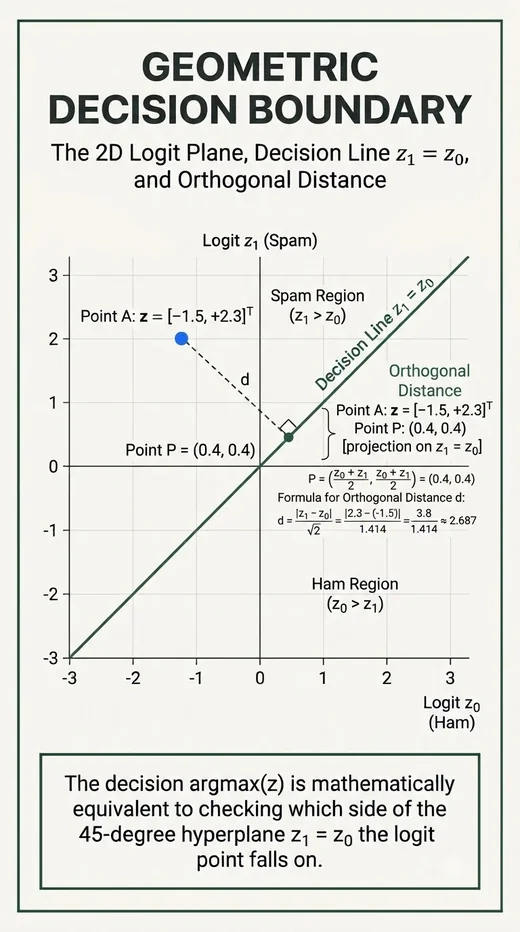
How are unnormalized scalar logits converted into discrete binary or multi-class decisions, and why is softmax mathematically redundant for argmax?
Open lesson →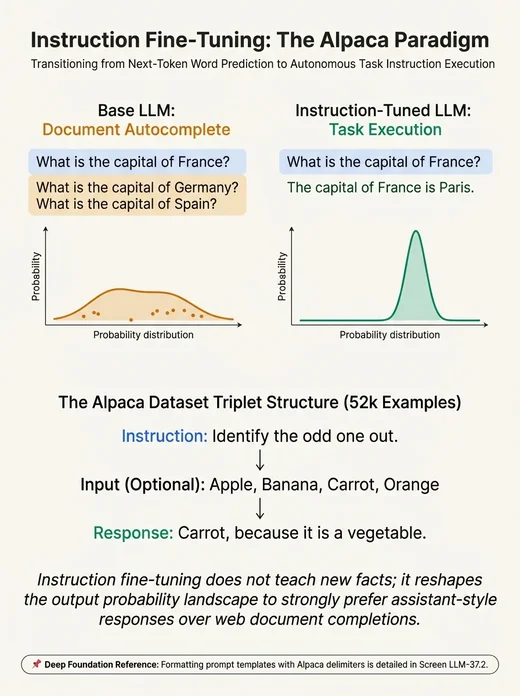
Master the complete Stanford Alpaca instruction finetuning pipeline: parse 52,000 JSON records, implement structured prompt templates, execute dynamic batch collation with prompt loss shielding, run the SFT training loop with cosine warmup, and benchmark qualitative responses.
Open lesson →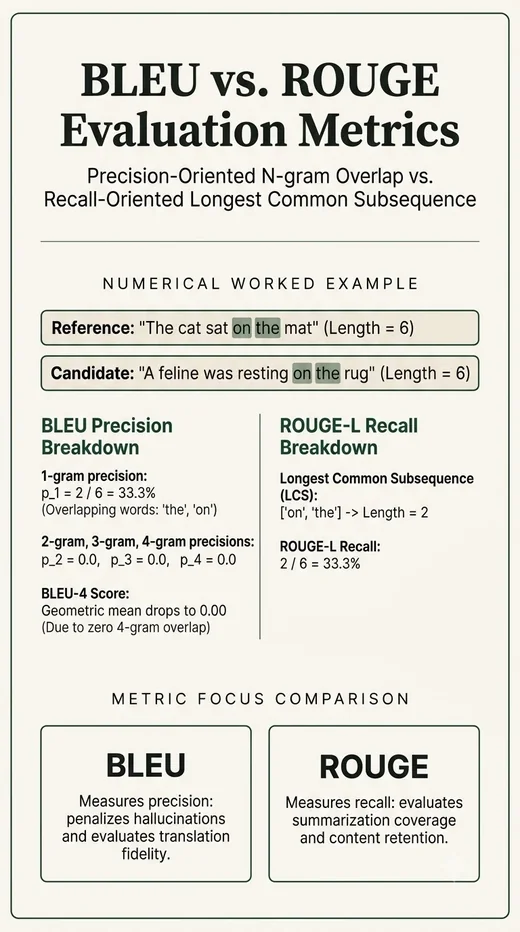
Why do traditional n-gram matching metrics like BLEU and ROUGE fail to fully capture generative LLM quality, and how do precision and recall trade off mathematically?
Open lesson →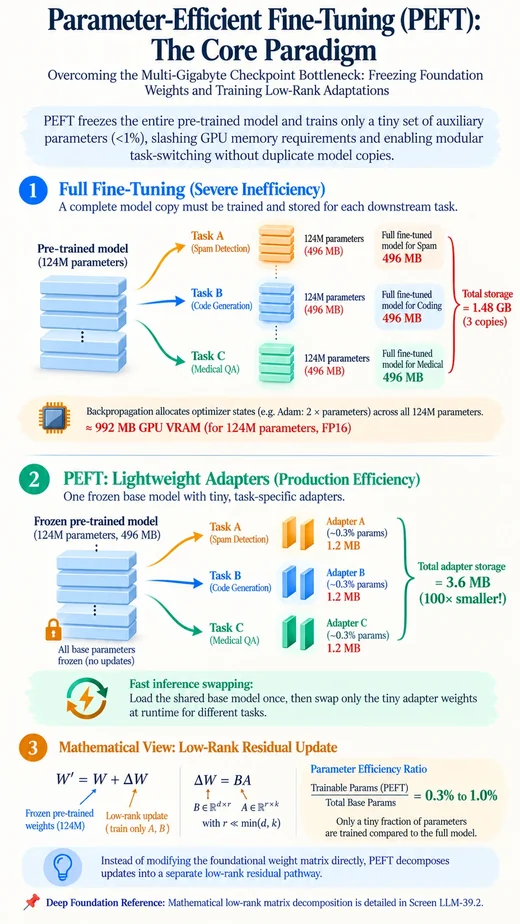
Why is full-parameter fine-tuning computationally prohibitive on modern GPUs, and how does PEFT solve the memory crisis?
Open lesson →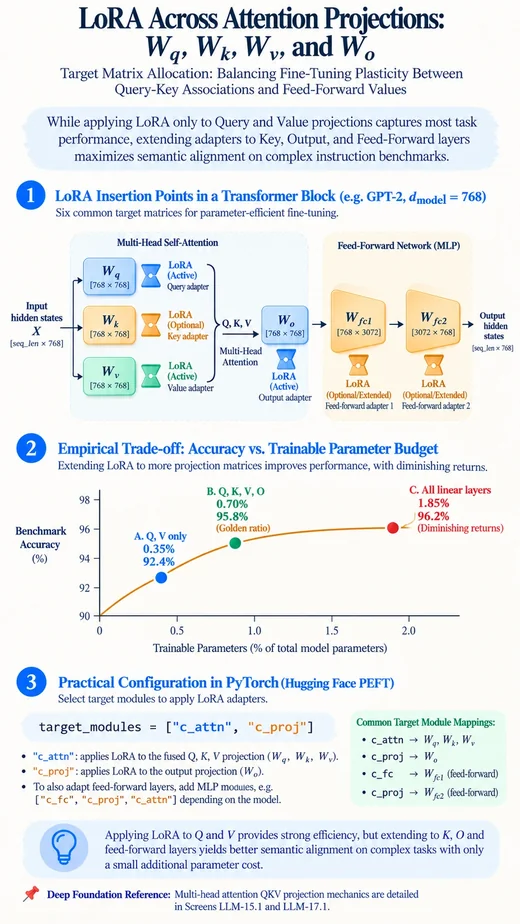
Which specific projection layers inside a transformer block yield the highest performance gains when adapted with LoRA?
Open lesson →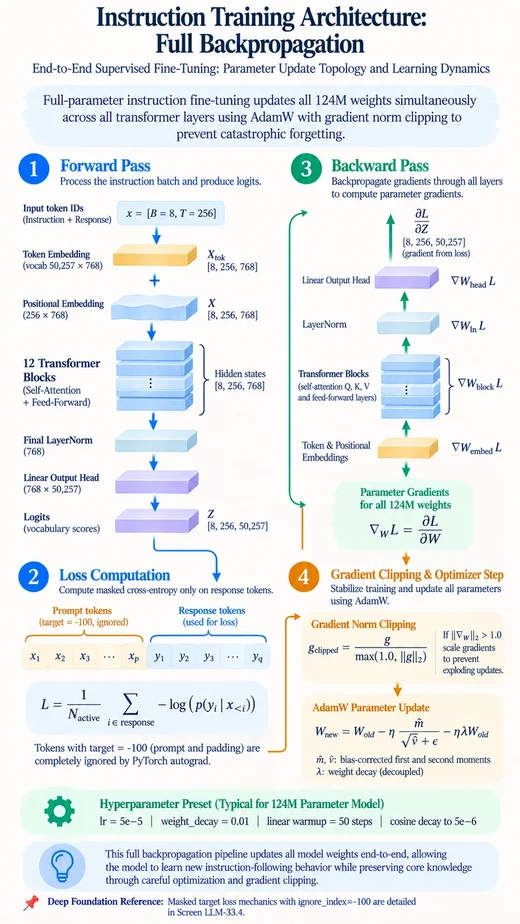
How is the complete instruction finetuning training loop structured in PyTorch with AdamW, learning rate schedules, and masked loss?
Open lesson →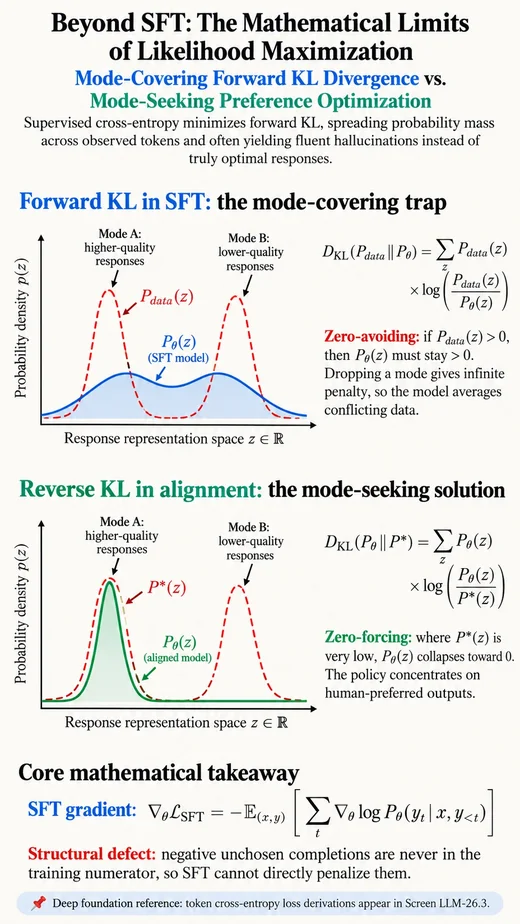
Why is supervised fine-tuning insufficient for aligning generative behavior, and why is a reference KL anchor required?
Open lesson →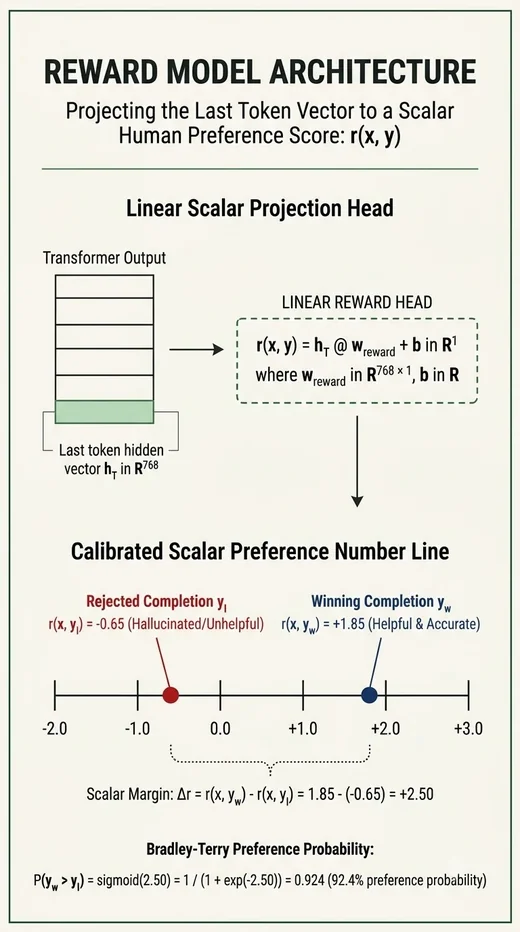
How is a generative autoregressive transformer modified into a scalar reward model, and how is it trained on preference pairs?
Open lesson →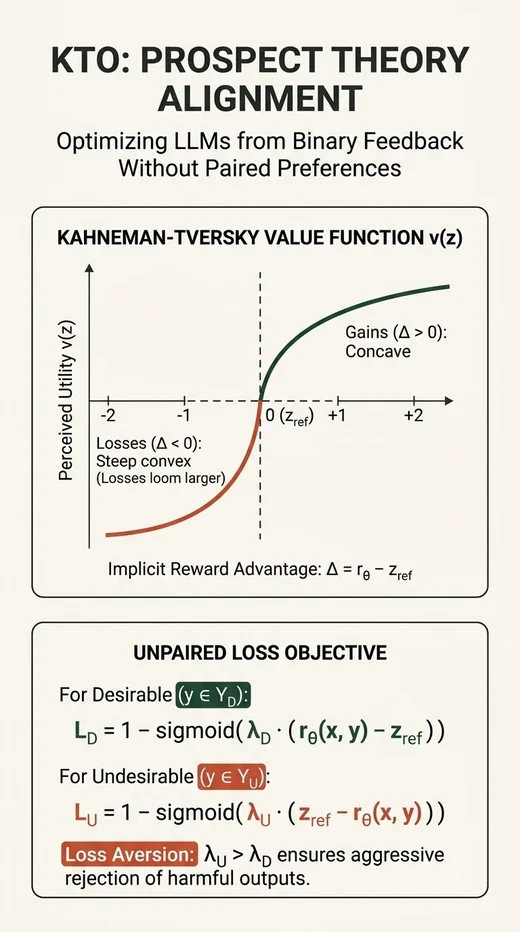
How does KTO align models using unpaired binary feedback (thumbs up / thumbs down) inspired by behavioral economics?
Open lesson →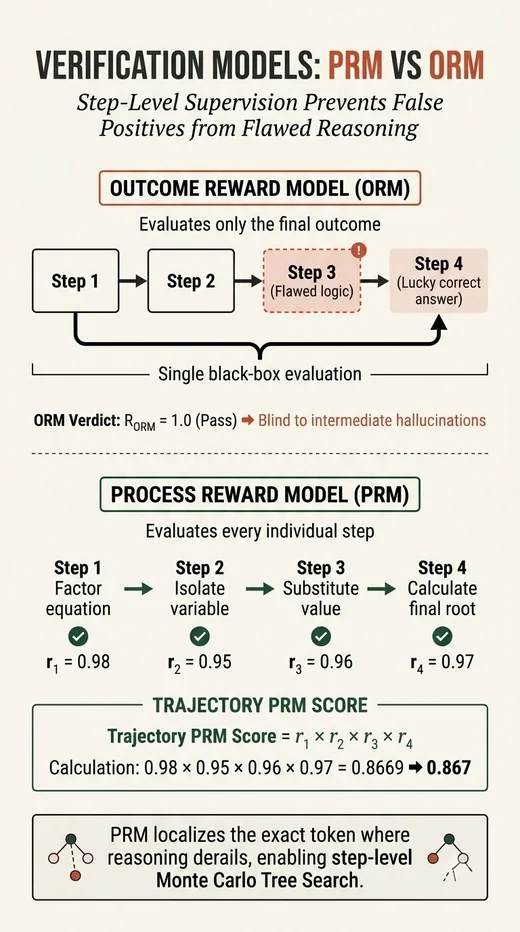
Why do Outcome Reward Models (ORMs) fail in multi-step reasoning, and how do Process Reward Models (PRMs) assign step-level credit?
Open lesson →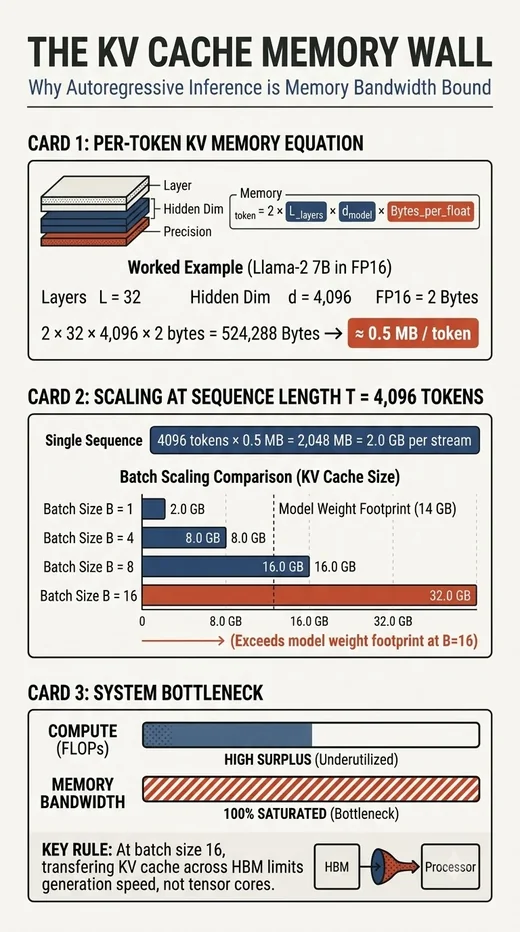
Why is autoregressive token generation bottlenecked by memory bandwidth rather than GPU compute, and how does the KV cache scale?
Open lesson →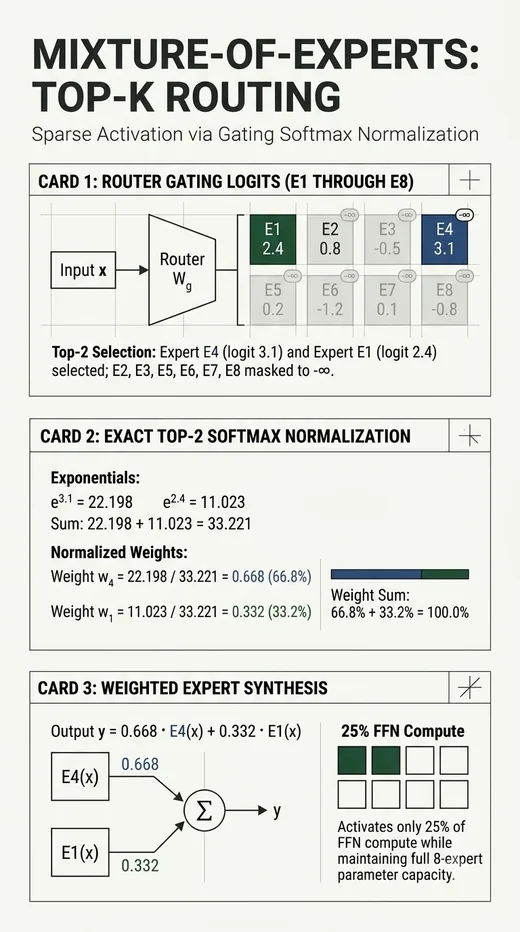
How does Sparse MoE scale total parameter capacity without increasing active FLOPs per token?
Open lesson →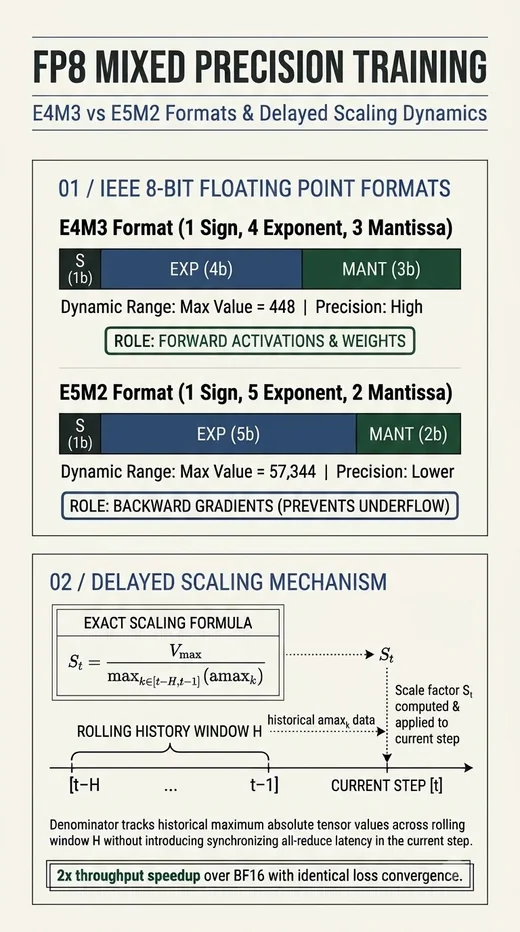
How does 8-bit floating point training double GPU GEMM throughput while preventing gradient underflow via delayed scaling?
Open lesson →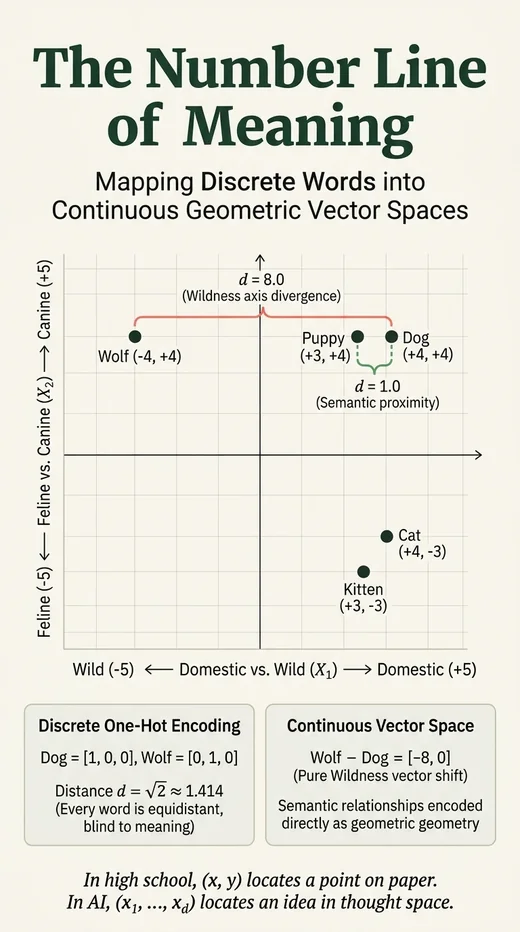
How does a 2D Cartesian plane turn discrete text words into continuous geometric thought space where distance measures meaning?
Open lesson →